Complete Results
These results are based on Bom (2019) data-generating mechanism with a total of 504 conditions.
Average Performance
Method performance measures are aggregated across all simulated conditions to provide an overall impression of method performance. However, keep in mind that a method with a high overall ranking is not necessarily the “best” method for a particular application. To select a suitable method for your application, consider also non-aggregated performance measures in conditions most relevant to your application.
| Rank | Method | Value | Rank | Method | Value |
|---|---|---|---|---|---|
| 1 | RoBMA (PSMA) | 0.219 | 1 | RoBMA (PSMA) | 0.219 |
| 2 | WILS (default) | 0.272 | 2 | WILS (default) | 0.272 |
| 3 | WAAPWLS (default) | 0.298 | 3 | WAAPWLS (default) | 0.298 |
| 4 | PEESE (default) | 0.299 | 4 | PEESE (default) | 0.299 |
| 5 | FMA (default) | 0.310 | 5 | FMA (default) | 0.310 |
| 5 | WLS (default) | 0.310 | 5 | WLS (default) | 0.310 |
| 7 | PETPEESE (default) | 0.330 | 7 | PETPEESE (default) | 0.330 |
| 8 | MMPH (default) | 0.336 | 8 | EK (default) | 0.338 |
| 9 | EK (default) | 0.338 | 9 | PET (default) | 0.340 |
| 10 | PET (default) | 0.340 | 10 | MMPH (default) | 0.343 |
| 11 | trimfill (default) | 0.362 | 11 | trimfill (default) | 0.362 |
| 12 | AK (AK2) | 0.384 | 12 | AK (AK2) | 0.451 |
| 13 | RMA (default) | 0.452 | 13 | RMA (default) | 0.452 |
| 14 | mean (default) | 0.481 | 14 | mean (default) | 0.481 |
| 15 | AK (AK1) | 0.533 | 15 | AK (AK1) | 0.522 |
| 16 | MAIVE (default) | 0.551 | 16 | MAIVE (default) | 0.551 |
| 17 | pcurve (default) | 0.596 | 17 | pcurve (default) | 0.569 |
| 18 | SM (3PSM) | 0.634 | 18 | SM (3PSM) | 0.629 |
| 19 | MAIVE (WAIVE) | 0.704 | 19 | RTMA (relaxed) | 0.636 |
| 20 | SM (4PSM) | 0.798 | 20 | MAIVE (WAIVE) | 0.704 |
| 21 | RTMA (relaxed) | 0.928 | 21 | SM (4PSM) | 0.789 |
| 22 | MAN (default) | 0.998 | 22 | MAN (default) | 0.912 |
| 23 | puniform (default) | 1.015 | 23 | puniform (default) | 0.964 |
| 24 | puniform (star) | 161.138 | 24 | puniform (star) | 161.138 |
RMSE (Root Mean Square Error) is an overall summary measure of estimation performance that combines bias and empirical SE. RMSE is the square root of the average squared difference between the meta-analytic estimate and the true effect across simulation runs. A lower RMSE indicates a better method.
| Rank | Method | Value | Rank | Method | Value |
|---|---|---|---|---|---|
| 1 | PET (default) | -0.015 | 1 | PET (default) | -0.015 |
| 2 | EK (default) | -0.015 | 2 | EK (default) | -0.015 |
| 3 | PETPEESE (default) | 0.041 | 3 | pcurve (default) | 0.031 |
| 4 | AK (AK2) | -0.044 | 4 | PETPEESE (default) | 0.041 |
| 5 | RoBMA (PSMA) | -0.063 | 5 | AK (AK2) | 0.051 |
| 6 | pcurve (default) | 0.072 | 6 | RoBMA (PSMA) | -0.063 |
| 7 | WILS (default) | -0.080 | 7 | WILS (default) | -0.080 |
| 8 | MAIVE (WAIVE) | 0.116 | 8 | RTMA (relaxed) | -0.083 |
| 9 | PEESE (default) | 0.133 | 9 | MAIVE (WAIVE) | 0.116 |
| 10 | MAIVE (default) | 0.142 | 10 | PEESE (default) | 0.133 |
| 11 | SM (4PSM) | -0.161 | 11 | MAIVE (default) | 0.142 |
| 12 | WAAPWLS (default) | 0.185 | 12 | SM (4PSM) | -0.163 |
| 13 | trimfill (default) | 0.185 | 13 | SM (3PSM) | -0.183 |
| 14 | SM (3PSM) | -0.189 | 14 | WAAPWLS (default) | 0.185 |
| 15 | FMA (default) | 0.207 | 15 | trimfill (default) | 0.185 |
| 16 | WLS (default) | 0.207 | 16 | FMA (default) | 0.207 |
| 17 | MMPH (default) | 0.227 | 17 | WLS (default) | 0.207 |
| 18 | AK (AK1) | 0.260 | 18 | MMPH (default) | 0.234 |
| 19 | RMA (default) | 0.360 | 19 | AK (AK1) | 0.260 |
| 20 | mean (default) | 0.388 | 20 | RMA (default) | 0.360 |
| 21 | puniform (default) | 0.744 | 21 | mean (default) | 0.388 |
| 22 | RTMA (relaxed) | -0.830 | 22 | puniform (default) | 0.751 |
| 23 | MAN (default) | -0.978 | 23 | MAN (default) | -0.786 |
| 24 | puniform (star) | -13.379 | 24 | puniform (star) | -13.379 |
Bias is the average difference between the meta-analytic estimate and the true effect across simulation runs. Ideally, this value should be close to 0.
| Rank | Method | Value | Rank | Method | Value |
|---|---|---|---|---|---|
| 1 | MMPH (default) | 0.145 | 1 | MMPH (default) | 0.148 |
| 2 | FMA (default) | 0.156 | 2 | FMA (default) | 0.156 |
| 2 | WLS (default) | 0.156 | 2 | WLS (default) | 0.156 |
| 4 | MAN (default) | 0.162 | 4 | WAAPWLS (default) | 0.168 |
| 5 | WAAPWLS (default) | 0.168 | 5 | RMA (default) | 0.174 |
| 6 | RMA (default) | 0.174 | 6 | mean (default) | 0.182 |
| 7 | mean (default) | 0.182 | 7 | RoBMA (PSMA) | 0.184 |
| 8 | RoBMA (PSMA) | 0.184 | 8 | PEESE (default) | 0.196 |
| 9 | pcurve (default) | 0.192 | 9 | pcurve (default) | 0.202 |
| 10 | PEESE (default) | 0.196 | 10 | trimfill (default) | 0.223 |
| 11 | trimfill (default) | 0.223 | 11 | WILS (default) | 0.238 |
| 12 | WILS (default) | 0.238 | 12 | MAN (default) | 0.250 |
| 13 | PETPEESE (default) | 0.281 | 13 | PETPEESE (default) | 0.281 |
| 14 | EK (default) | 0.307 | 14 | EK (default) | 0.307 |
| 15 | PET (default) | 0.309 | 15 | PET (default) | 0.309 |
| 16 | AK (AK1) | 0.343 | 16 | AK (AK1) | 0.333 |
| 17 | RTMA (relaxed) | 0.349 | 17 | puniform (default) | 0.353 |
| 18 | AK (AK2) | 0.369 | 18 | MAIVE (default) | 0.394 |
| 19 | MAIVE (default) | 0.394 | 19 | AK (AK2) | 0.410 |
| 20 | puniform (default) | 0.401 | 20 | RTMA (relaxed) | 0.525 |
| 21 | SM (3PSM) | 0.576 | 21 | SM (3PSM) | 0.571 |
| 22 | MAIVE (WAIVE) | 0.598 | 22 | MAIVE (WAIVE) | 0.598 |
| 23 | SM (4PSM) | 0.766 | 23 | SM (4PSM) | 0.756 |
| 24 | puniform (star) | 160.321 | 24 | puniform (star) | 160.321 |
The empirical SE is the standard deviation of the meta-analytic estimate across simulation runs. A lower empirical SE indicates less variability and better method performance.
| Rank | Method | Value | Rank | Method | Value |
|---|---|---|---|---|---|
| 1 | RoBMA (PSMA) | 1.384 | 1 | RoBMA (PSMA) | 1.384 |
| 2 | EK (default) | 1.927 | 2 | EK (default) | 1.927 |
| 3 | PET (default) | 2.029 | 3 | PET (default) | 2.029 |
| 4 | AK (AK2) | 2.249 | 4 | WILS (default) | 2.796 |
| 5 | WILS (default) | 2.796 | 5 | PETPEESE (default) | 2.960 |
| 6 | PETPEESE (default) | 2.960 | 6 | SM (3PSM) | 3.040 |
| 7 | SM (3PSM) | 3.099 | 7 | puniform (star) | 3.290 |
| 8 | puniform (star) | 3.290 | 8 | SM (4PSM) | 3.405 |
| 9 | PEESE (default) | 3.641 | 9 | PEESE (default) | 3.641 |
| 10 | WAAPWLS (default) | 4.392 | 10 | AK (AK2) | 3.988 |
| 11 | MAIVE (WAIVE) | 4.624 | 11 | WAAPWLS (default) | 4.392 |
| 12 | trimfill (default) | 4.637 | 12 | MAIVE (WAIVE) | 4.624 |
| 13 | WLS (default) | 5.227 | 13 | trimfill (default) | 4.637 |
| 14 | MAIVE (default) | 5.405 | 14 | WLS (default) | 5.227 |
| 15 | MMPH (default) | 5.776 | 15 | MAIVE (default) | 5.405 |
| 16 | SM (4PSM) | 5.934 | 16 | MMPH (default) | 5.994 |
| 17 | RMA (default) | 8.106 | 17 | RTMA (relaxed) | 7.142 |
| 18 | FMA (default) | 8.872 | 18 | RMA (default) | 8.106 |
| 19 | RTMA (relaxed) | 10.538 | 19 | FMA (default) | 8.872 |
| 20 | AK (AK1) | 11.720 | 20 | AK (AK1) | 10.803 |
| 21 | mean (default) | 14.294 | 21 | mean (default) | 14.294 |
| 22 | puniform (default) | 23.303 | 22 | puniform (default) | 23.166 |
| 23 | MAN (default) | 26.694 | 23 | MAN (default) | 24.426 |
| 24 | pcurve (default) | NaN | 24 | pcurve (default) | NaN |
The interval score measures the accuracy of a confidence interval by combining its width and coverage. It penalizes intervals that are too wide or that fail to include the true value. A lower interval score indicates a better method.
| Rank | Method | Value | Rank | Method | Value |
|---|---|---|---|---|---|
| 1 | RoBMA (PSMA) | 0.952 | 1 | RoBMA (PSMA) | 0.952 |
| 2 | AK (AK2) | 0.933 | 2 | SM (4PSM) | 0.911 |
| 3 | SM (4PSM) | 0.913 | 3 | SM (3PSM) | 0.888 |
| 4 | SM (3PSM) | 0.891 | 4 | puniform (star) | 0.882 |
| 5 | puniform (star) | 0.882 | 5 | AK (AK2) | 0.880 |
| 6 | EK (default) | 0.876 | 6 | EK (default) | 0.876 |
| 7 | PET (default) | 0.852 | 7 | PET (default) | 0.852 |
| 8 | MAIVE (WAIVE) | 0.846 | 8 | MAIVE (WAIVE) | 0.846 |
| 9 | MAIVE (default) | 0.833 | 9 | MAIVE (default) | 0.833 |
| 10 | RTMA (relaxed) | 0.821 | 10 | PETPEESE (default) | 0.796 |
| 11 | PETPEESE (default) | 0.796 | 11 | RTMA (relaxed) | 0.742 |
| 12 | MMPH (default) | 0.692 | 12 | WILS (default) | 0.674 |
| 13 | WILS (default) | 0.674 | 13 | MMPH (default) | 0.664 |
| 14 | AK (AK1) | 0.632 | 14 | AK (AK1) | 0.632 |
| 15 | PEESE (default) | 0.632 | 15 | PEESE (default) | 0.632 |
| 16 | trimfill (default) | 0.609 | 16 | trimfill (default) | 0.609 |
| 17 | WAAPWLS (default) | 0.599 | 17 | WAAPWLS (default) | 0.599 |
| 18 | RMA (default) | 0.560 | 18 | RMA (default) | 0.560 |
| 19 | WLS (default) | 0.557 | 19 | WLS (default) | 0.557 |
| 20 | puniform (default) | 0.373 | 20 | puniform (default) | 0.374 |
| 21 | FMA (default) | 0.329 | 21 | FMA (default) | 0.329 |
| 22 | mean (default) | 0.308 | 22 | mean (default) | 0.308 |
| 23 | MAN (default) | 0.195 | 23 | MAN (default) | 0.291 |
| 24 | pcurve (default) | NaN | 24 | pcurve (default) | NaN |
95% CI coverage is the proportion of simulation runs in which the 95% confidence interval contained the true effect. Ideally, this value should be close to the nominal level of 95%.
| Rank | Method | Value | Rank | Method | Value |
|---|---|---|---|---|---|
| 1 | FMA (default) | 0.154 | 1 | FMA (default) | 0.154 |
| 2 | mean (default) | 0.228 | 2 | mean (default) | 0.228 |
| 3 | WLS (default) | 0.535 | 3 | WLS (default) | 0.535 |
| 4 | WILS (default) | 0.566 | 4 | WILS (default) | 0.566 |
| 5 | WAAPWLS (default) | 0.601 | 5 | WAAPWLS (default) | 0.601 |
| 6 | MMPH (default) | 0.646 | 6 | MMPH (default) | 0.645 |
| 7 | PEESE (default) | 0.660 | 7 | MAN (default) | 0.655 |
| 8 | MAN (default) | 0.690 | 8 | PEESE (default) | 0.660 |
| 9 | RoBMA (PSMA) | 0.841 | 9 | puniform (default) | 0.812 |
| 10 | trimfill (default) | 0.845 | 10 | RoBMA (PSMA) | 0.841 |
| 11 | RMA (default) | 0.872 | 11 | trimfill (default) | 0.845 |
| 12 | puniform (star) | 0.894 | 12 | RMA (default) | 0.872 |
| 13 | puniform (default) | 0.907 | 13 | puniform (star) | 0.894 |
| 14 | PETPEESE (default) | 0.995 | 14 | PETPEESE (default) | 0.995 |
| 15 | PET (default) | 1.139 | 15 | PET (default) | 1.139 |
| 16 | EK (default) | 1.424 | 16 | EK (default) | 1.424 |
| 17 | AK (AK2) | 1.883 | 17 | RTMA (relaxed) | 1.640 |
| 18 | MAIVE (default) | 1.945 | 18 | MAIVE (default) | 1.945 |
| 19 | MAIVE (WAIVE) | 2.067 | 19 | SM (3PSM) | 2.049 |
| 20 | SM (3PSM) | 2.198 | 20 | MAIVE (WAIVE) | 2.067 |
| 21 | RTMA (relaxed) | 4.125 | 21 | SM (4PSM) | 2.684 |
| 22 | SM (4PSM) | 5.218 | 22 | AK (AK2) | 2.716 |
| 23 | AK (AK1) | 6.939 | 23 | AK (AK1) | 6.022 |
| 24 | pcurve (default) | NaN | 24 | pcurve (default) | NaN |
95% CI width is the average length of the 95% confidence interval for the true effect. A lower average 95% CI length indicates a better method.
| Rank | Method | Log Value | Rank | Method | Log Value |
|---|---|---|---|---|---|
| 1 | RoBMA (PSMA) | 5.057 | 1 | RoBMA (PSMA) | 5.057 |
| 2 | AK (AK2) | 2.941 | 2 | EK (default) | 2.664 |
| 3 | EK (default) | 2.664 | 3 | PET (default) | 2.663 |
| 4 | PET (default) | 2.663 | 4 | PETPEESE (default) | 2.456 |
| 5 | PETPEESE (default) | 2.456 | 5 | MAIVE (default) | 2.417 |
| 6 | MAIVE (default) | 2.417 | 6 | MAIVE (WAIVE) | 2.359 |
| 7 | MAIVE (WAIVE) | 2.359 | 7 | AK (AK2) | 2.249 |
| 8 | puniform (star) | 2.109 | 8 | SM (4PSM) | 2.184 |
| 9 | SM (4PSM) | 2.103 | 9 | puniform (star) | 2.109 |
| 10 | SM (3PSM) | 1.949 | 10 | SM (3PSM) | 1.972 |
| 11 | MMPH (default) | 1.819 | 11 | RTMA (relaxed) | 1.626 |
| 12 | RTMA (relaxed) | 1.456 | 12 | MMPH (default) | 1.558 |
| 13 | AK (AK1) | 1.327 | 13 | WILS (default) | 1.326 |
| 14 | WILS (default) | 1.326 | 14 | AK (AK1) | 1.325 |
| 15 | PEESE (default) | 1.164 | 15 | PEESE (default) | 1.164 |
| 16 | WAAPWLS (default) | 1.158 | 16 | WAAPWLS (default) | 1.158 |
| 17 | RMA (default) | 1.079 | 17 | RMA (default) | 1.079 |
| 18 | trimfill (default) | 1.030 | 18 | trimfill (default) | 1.030 |
| 19 | WLS (default) | 1.010 | 19 | WLS (default) | 1.010 |
| 20 | puniform (default) | 0.528 | 20 | puniform (default) | 0.530 |
| 21 | FMA (default) | 0.423 | 21 | MAN (default) | 0.450 |
| 22 | mean (default) | 0.391 | 22 | FMA (default) | 0.423 |
| 23 | MAN (default) | 0.216 | 23 | mean (default) | 0.391 |
| 24 | pcurve (default) | NaN | 24 | pcurve (default) | NaN |
The positive likelihood ratio is an overall summary measure of hypothesis testing performance that combines power and type I error rate. It indicates how much a significant test result changes the odds of the alternative hypothesis versus the null hypothesis. A useful method has a positive likelihood ratio greater than 1 (or a log positive likelihood ratio greater than 0). A higher (log) positive likelihood ratio indicates a better method.
| Rank | Method | Log Value | Rank | Method | Log Value |
|---|---|---|---|---|---|
| 1 | PETPEESE (default) | -4.980 | 1 | PETPEESE (default) | -4.980 |
| 2 | PET (default) | -4.830 | 2 | AK (AK2) | -4.901 |
| 3 | EK (default) | -4.830 | 3 | PET (default) | -4.830 |
| 4 | SM (3PSM) | -4.506 | 4 | EK (default) | -4.830 |
| 5 | MAIVE (default) | -4.315 | 5 | SM (3PSM) | -4.576 |
| 6 | WILS (default) | -4.255 | 6 | SM (4PSM) | -4.332 |
| 7 | puniform (star) | -4.175 | 7 | MAIVE (default) | -4.315 |
| 8 | MMPH (default) | -4.141 | 8 | WILS (default) | -4.255 |
| 9 | WAAPWLS (default) | -3.973 | 9 | puniform (star) | -4.175 |
| 10 | RoBMA (PSMA) | -3.921 | 10 | MMPH (default) | -4.141 |
| 11 | PEESE (default) | -3.884 | 11 | WAAPWLS (default) | -3.973 |
| 12 | SM (4PSM) | -3.803 | 12 | RoBMA (PSMA) | -3.921 |
| 13 | AK (AK2) | -3.707 | 13 | PEESE (default) | -3.884 |
| 14 | trimfill (default) | -3.441 | 14 | trimfill (default) | -3.441 |
| 15 | WLS (default) | -3.338 | 15 | WLS (default) | -3.338 |
| 16 | MAIVE (WAIVE) | -3.228 | 16 | MAIVE (WAIVE) | -3.228 |
| 17 | AK (AK1) | -3.142 | 17 | AK (AK1) | -3.142 |
| 18 | RMA (default) | -3.006 | 18 | RTMA (relaxed) | -3.035 |
| 19 | FMA (default) | -2.869 | 19 | RMA (default) | -3.006 |
| 20 | puniform (default) | -2.752 | 20 | FMA (default) | -2.869 |
| 21 | mean (default) | -2.536 | 21 | puniform (default) | -2.757 |
| 22 | RTMA (relaxed) | -1.698 | 22 | mean (default) | -2.536 |
| 23 | MAN (default) | -0.302 | 23 | MAN (default) | -1.011 |
| 24 | pcurve (default) | NaN | 24 | pcurve (default) | NaN |
The negative likelihood ratio is an overall summary measure of hypothesis testing performance that combines power and type I error rate. It indicates how much a non-significant test result changes the odds of the alternative hypothesis versus the null hypothesis. A useful method has a negative likelihood ratio less than 1 (or a log negative likelihood ratio less than 0). A lower (log) negative likelihood ratio indicates a better method.
| Rank | Method | Value | Rank | Method | Value |
|---|---|---|---|---|---|
| 1 | RoBMA (PSMA) | 0.020 | 1 | RoBMA (PSMA) | 0.020 |
| 2 | AK (AK2) | 0.048 | 2 | SM (4PSM) | 0.097 |
| 3 | SM (4PSM) | 0.098 | 3 | SM (3PSM) | 0.119 |
| 4 | SM (3PSM) | 0.118 | 4 | MAIVE (WAIVE) | 0.131 |
| 5 | MAIVE (WAIVE) | 0.131 | 5 | PET (default) | 0.135 |
| 6 | PET (default) | 0.135 | 6 | EK (default) | 0.135 |
| 7 | EK (default) | 0.135 | 7 | AK (AK2) | 0.150 |
| 8 | RTMA (relaxed) | 0.153 | 8 | PETPEESE (default) | 0.161 |
| 9 | PETPEESE (default) | 0.161 | 9 | puniform (star) | 0.198 |
| 10 | puniform (star) | 0.198 | 10 | MAIVE (default) | 0.222 |
| 11 | MAIVE (default) | 0.222 | 11 | RTMA (relaxed) | 0.254 |
| 12 | WILS (default) | 0.264 | 12 | WILS (default) | 0.264 |
| 13 | MMPH (default) | 0.392 | 13 | MMPH (default) | 0.444 |
| 14 | PEESE (default) | 0.477 | 14 | PEESE (default) | 0.477 |
| 15 | WAAPWLS (default) | 0.504 | 15 | WAAPWLS (default) | 0.504 |
| 16 | trimfill (default) | 0.516 | 16 | trimfill (default) | 0.516 |
| 17 | AK (AK1) | 0.555 | 17 | AK (AK1) | 0.555 |
| 18 | WLS (default) | 0.573 | 18 | WLS (default) | 0.573 |
| 19 | RMA (default) | 0.583 | 19 | RMA (default) | 0.583 |
| 20 | MAN (default) | 0.629 | 20 | MAN (default) | 0.629 |
| 21 | puniform (default) | 0.757 | 21 | puniform (default) | 0.755 |
| 22 | FMA (default) | 0.795 | 22 | FMA (default) | 0.795 |
| 23 | mean (default) | 0.806 | 23 | mean (default) | 0.806 |
| 24 | pcurve (default) | NaN | 24 | pcurve (default) | NaN |
The type I error rate is the proportion of simulation runs in which the null hypothesis of no effect was incorrectly rejected when it was true. Ideally, this value should be close to the nominal level of 5%.
| Rank | Method | Value | Rank | Method | Value |
|---|---|---|---|---|---|
| 1 | puniform (default) | 0.998 | 1 | puniform (default) | 0.998 |
| 2 | mean (default) | 0.994 | 2 | mean (default) | 0.994 |
| 3 | FMA (default) | 0.994 | 3 | FMA (default) | 0.994 |
| 4 | WLS (default) | 0.945 | 4 | WLS (default) | 0.945 |
| 5 | AK (AK1) | 0.940 | 5 | AK (AK1) | 0.940 |
| 6 | RMA (default) | 0.933 | 6 | RMA (default) | 0.933 |
| 7 | WAAPWLS (default) | 0.926 | 7 | WAAPWLS (default) | 0.926 |
| 8 | MMPH (default) | 0.924 | 8 | MMPH (default) | 0.924 |
| 9 | PEESE (default) | 0.919 | 9 | PEESE (default) | 0.919 |
| 10 | trimfill (default) | 0.914 | 10 | trimfill (default) | 0.914 |
| 11 | PETPEESE (default) | 0.859 | 11 | PETPEESE (default) | 0.859 |
| 12 | puniform (star) | 0.852 | 12 | MAN (default) | 0.856 |
| 13 | WILS (default) | 0.848 | 13 | puniform (star) | 0.852 |
| 14 | MAIVE (default) | 0.834 | 14 | AK (AK2) | 0.849 |
| 15 | EK (default) | 0.826 | 15 | WILS (default) | 0.848 |
| 16 | PET (default) | 0.826 | 16 | MAIVE (default) | 0.834 |
| 17 | AK (AK2) | 0.793 | 17 | EK (default) | 0.826 |
| 18 | MAN (default) | 0.771 | 18 | PET (default) | 0.826 |
| 19 | SM (3PSM) | 0.763 | 19 | RTMA (relaxed) | 0.814 |
| 20 | SM (4PSM) | 0.744 | 20 | SM (4PSM) | 0.774 |
| 21 | MAIVE (WAIVE) | 0.742 | 21 | SM (3PSM) | 0.773 |
| 22 | RoBMA (PSMA) | 0.684 | 22 | MAIVE (WAIVE) | 0.742 |
| 23 | RTMA (relaxed) | 0.460 | 23 | RoBMA (PSMA) | 0.684 |
| 24 | pcurve (default) | NaN | 24 | pcurve (default) | NaN |
The power is the proportion of simulation runs in which the null hypothesis of no effect was correctly rejected when the alternative hypothesis was true. A higher power indicates a better method.
By-Condition Performance (Conditional on Method Convergence)
The results below are conditional on method convergence. Note that the methods might differ in convergence rate and are therefore not compared on the same data sets.
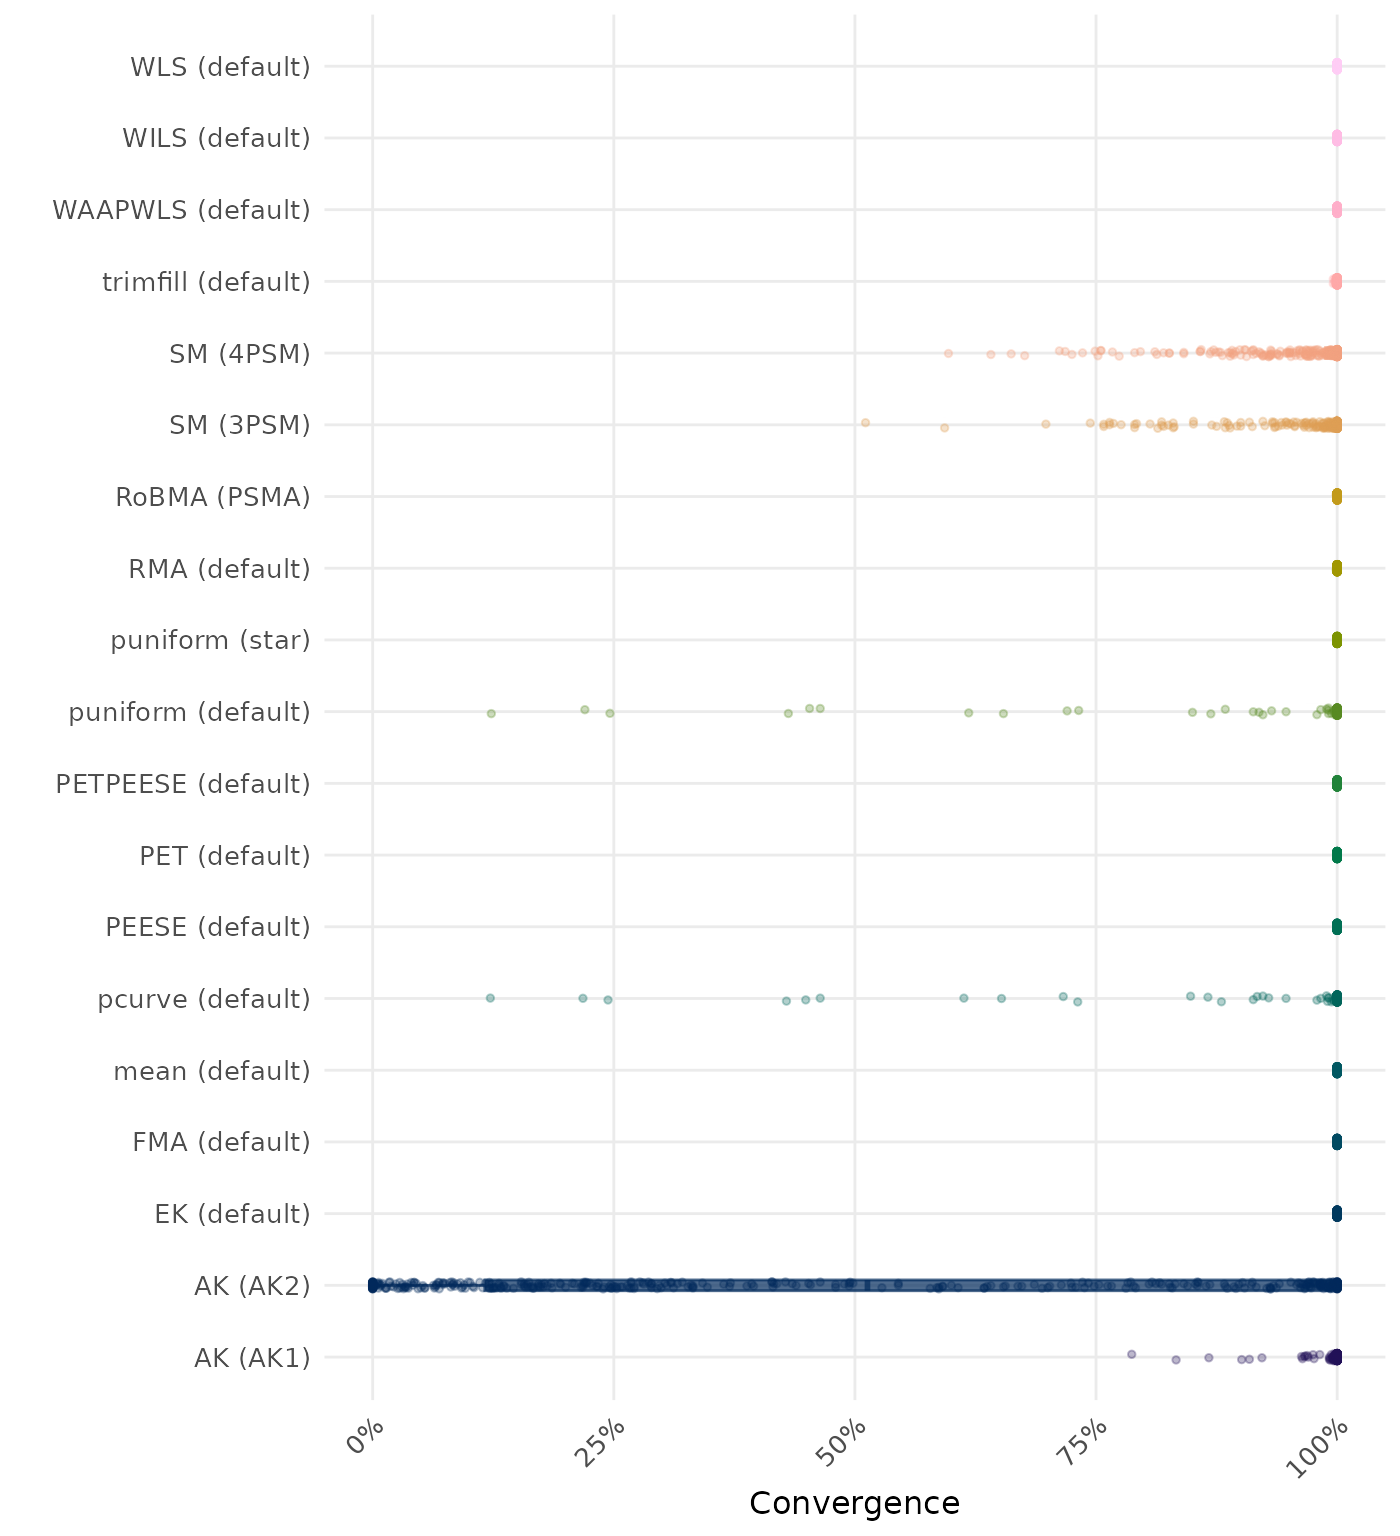
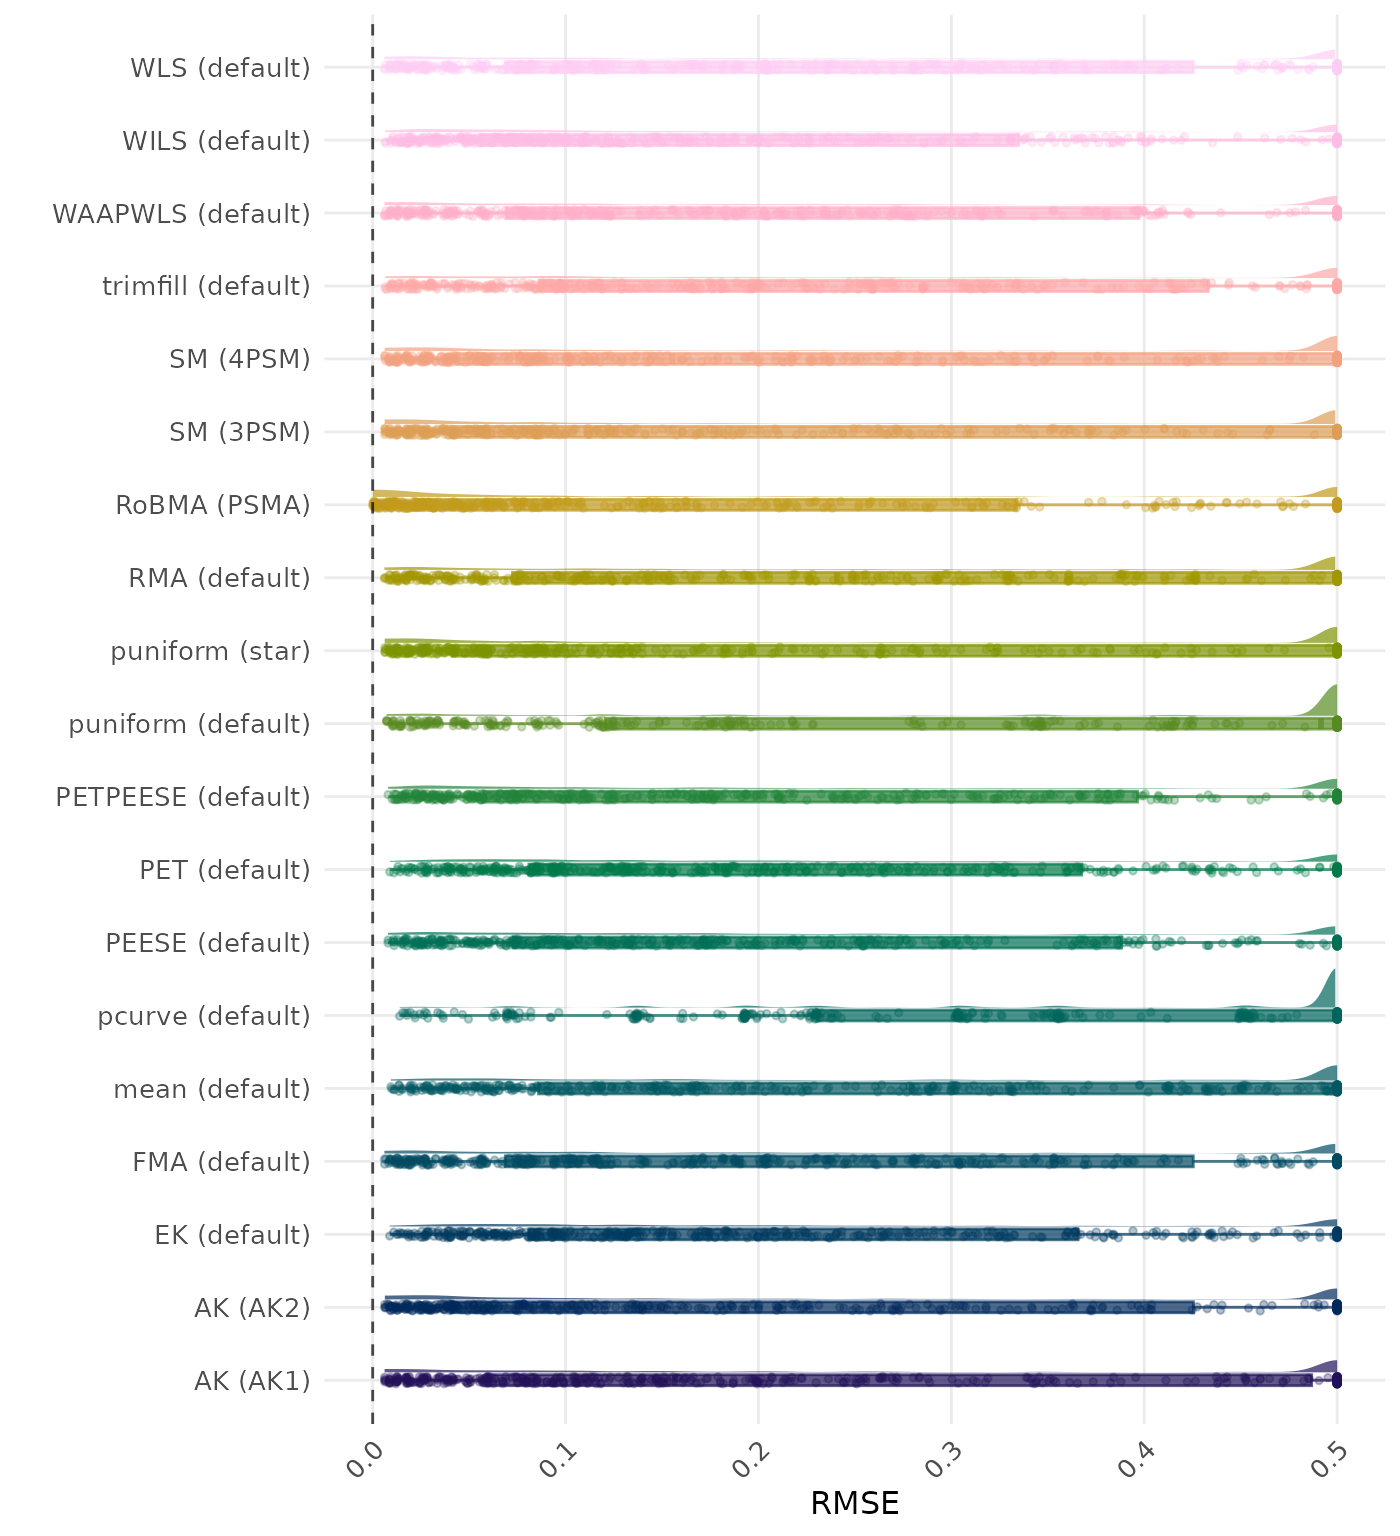
RMSE (Root Mean Square Error) is an overall summary measure of estimation performance that combines bias and empirical SE. RMSE is the square root of the average squared difference between the meta-analytic estimate and the true effect across simulation runs. A lower RMSE indicates a better method. Values larger than 0.5 are visualized as 0.5.
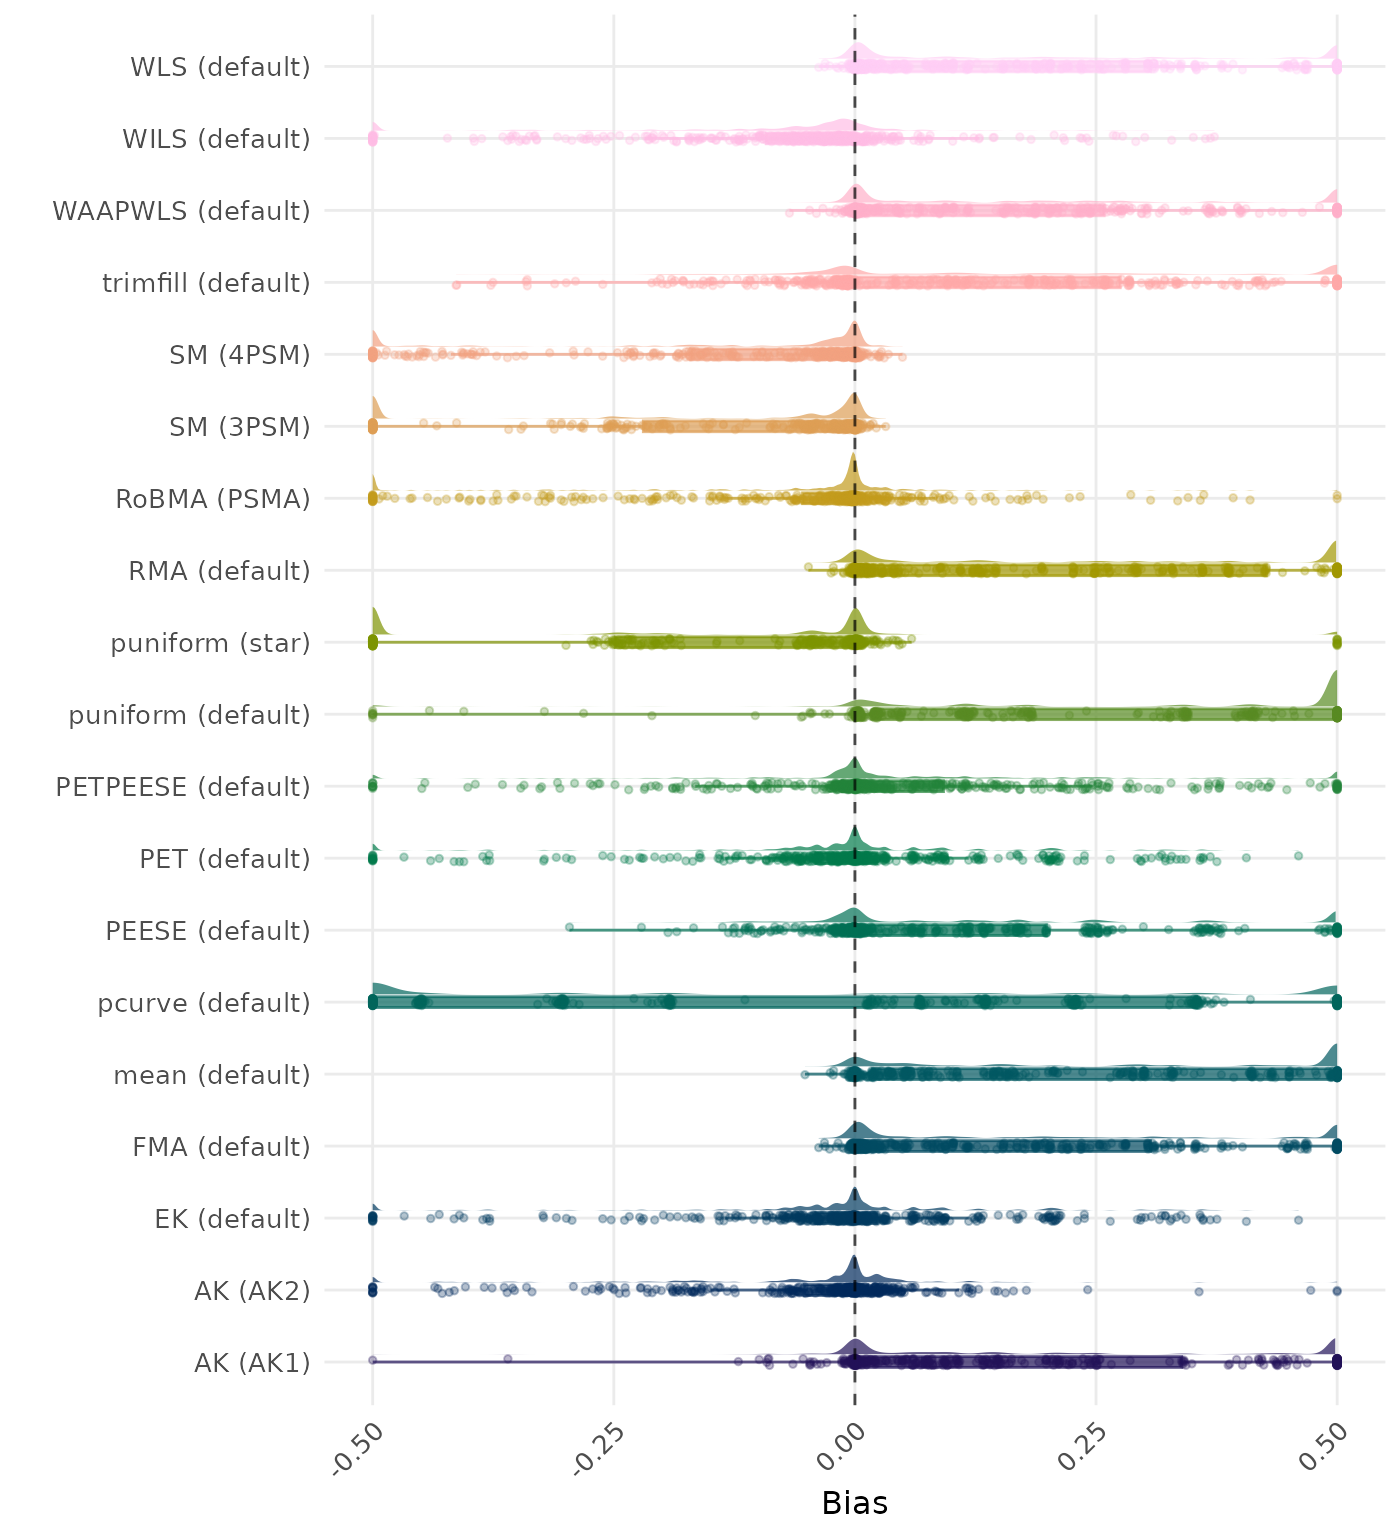
Bias is the average difference between the meta-analytic estimate and the true effect across simulation runs. Ideally, this value should be close to 0. Values lower than -0.5 or larger than 0.5 are visualized as -0.5 and 0.5 respectively.
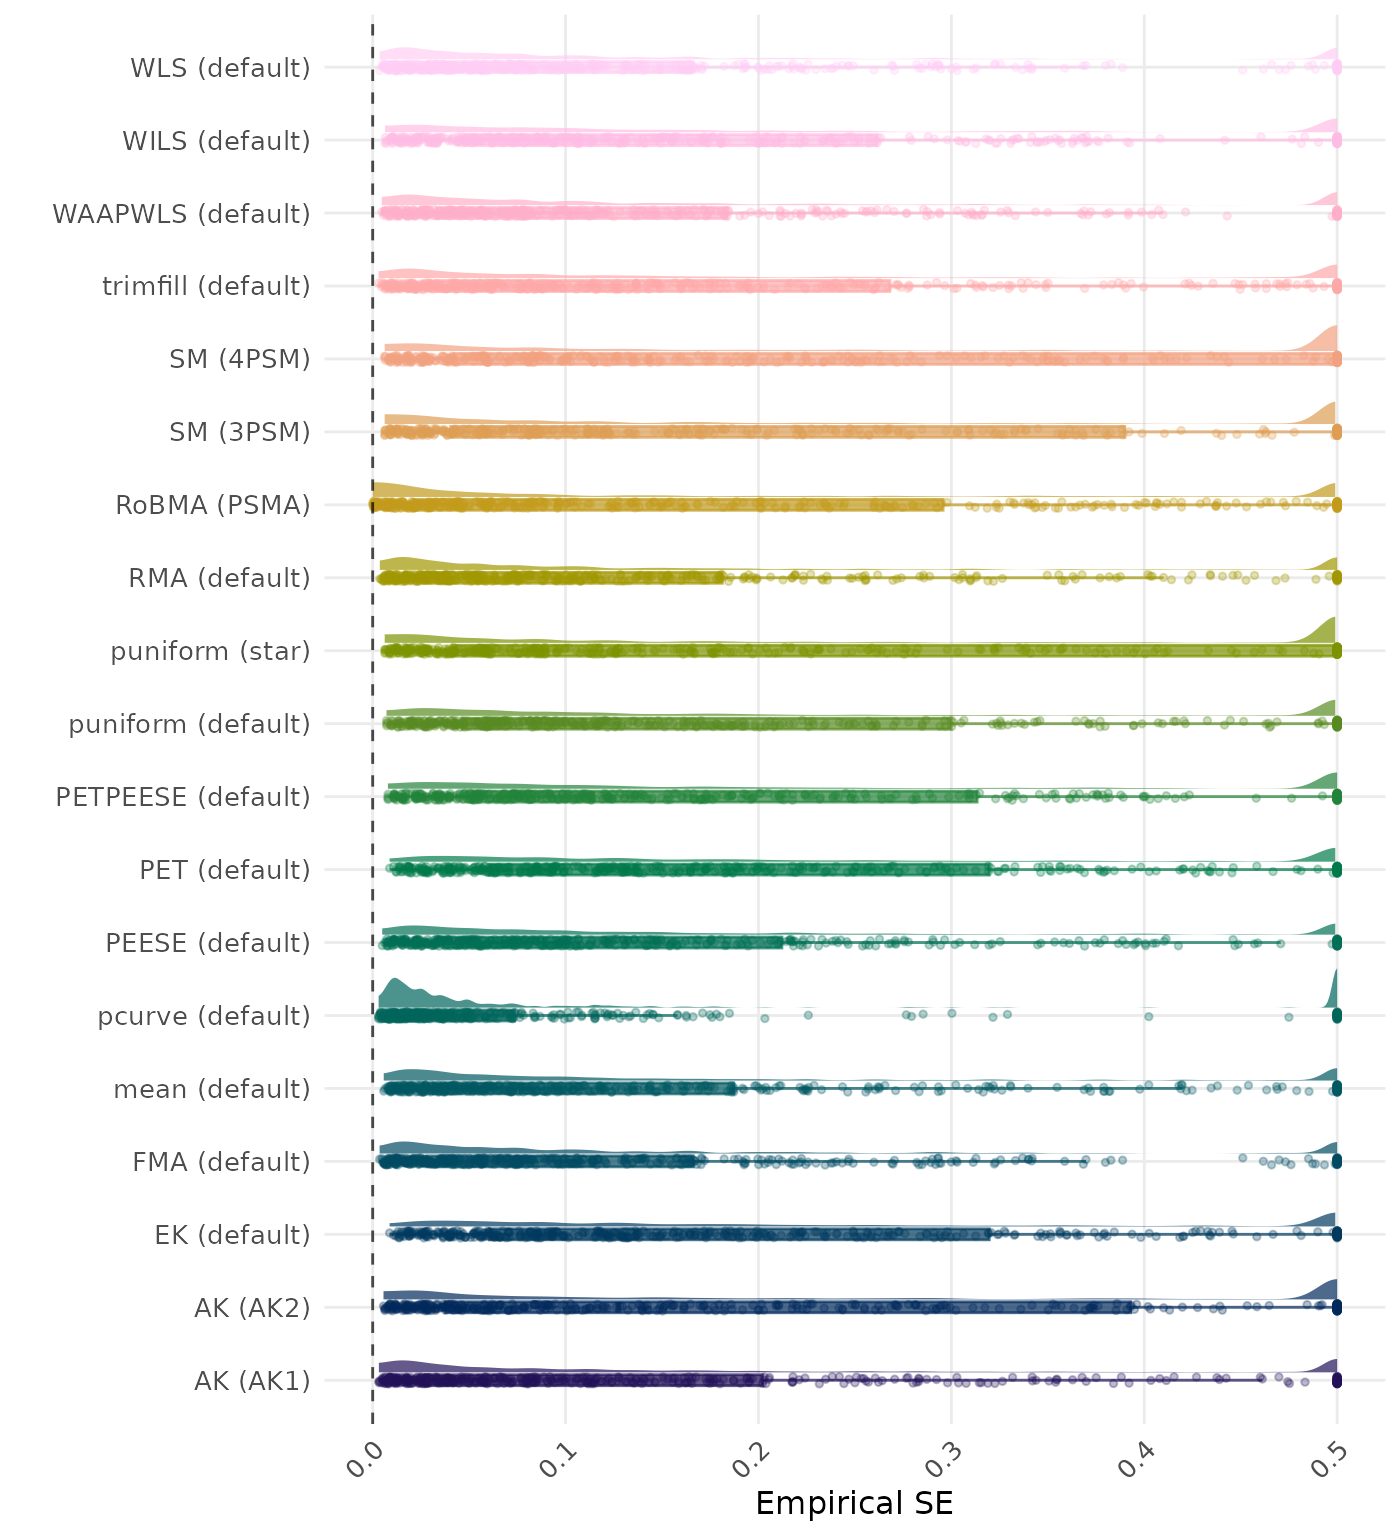
The empirical SE is the standard deviation of the meta-analytic estimate across simulation runs. A lower empirical SE indicates less variability and better method performance. Values larger than 0.5 are visualized as 0.5.
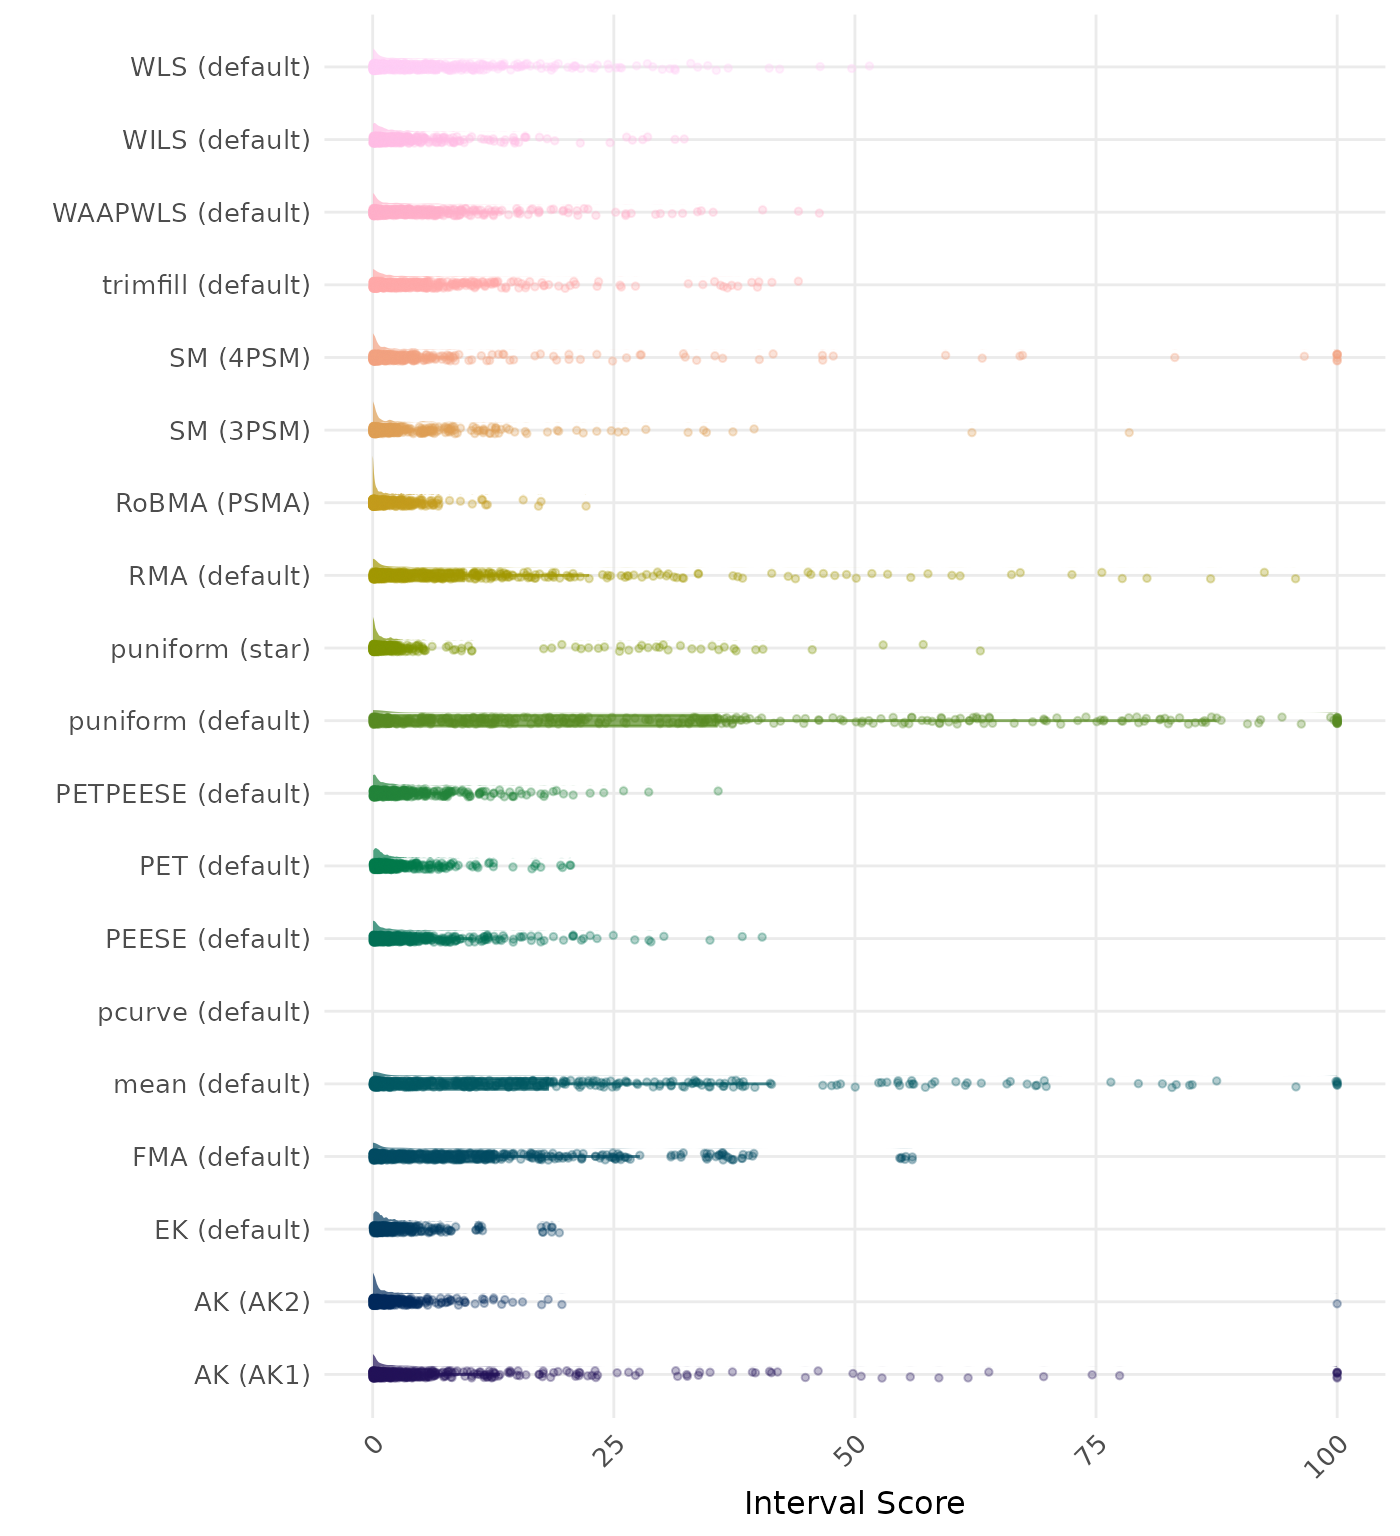
The interval score measures the accuracy of a confidence interval by combining its width and coverage. It penalizes intervals that are too wide or that fail to include the true value. A lower interval score indicates a better method. Values larger than 100 are visualized as 100.
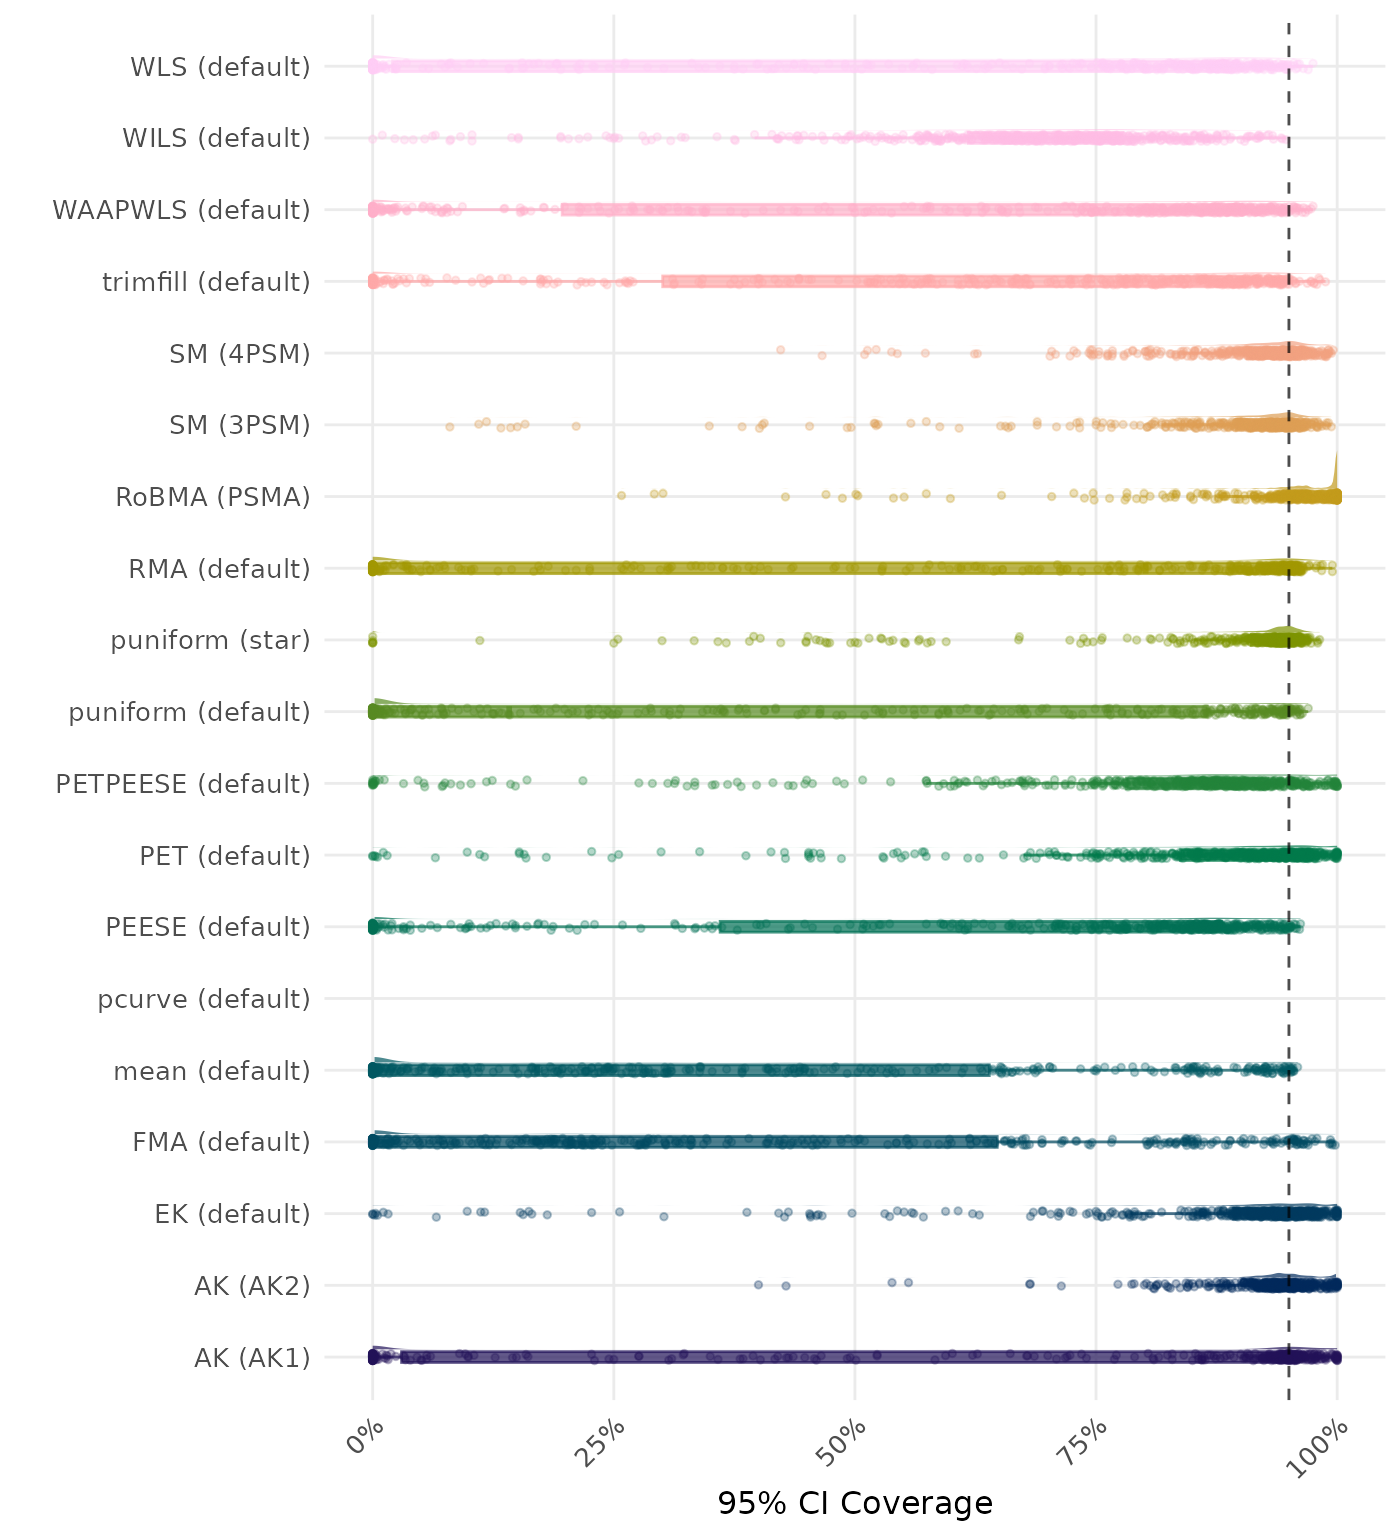
95% CI coverage is the proportion of simulation runs in which the 95% confidence interval contained the true effect. Ideally, this value should be close to the nominal level of 95%.
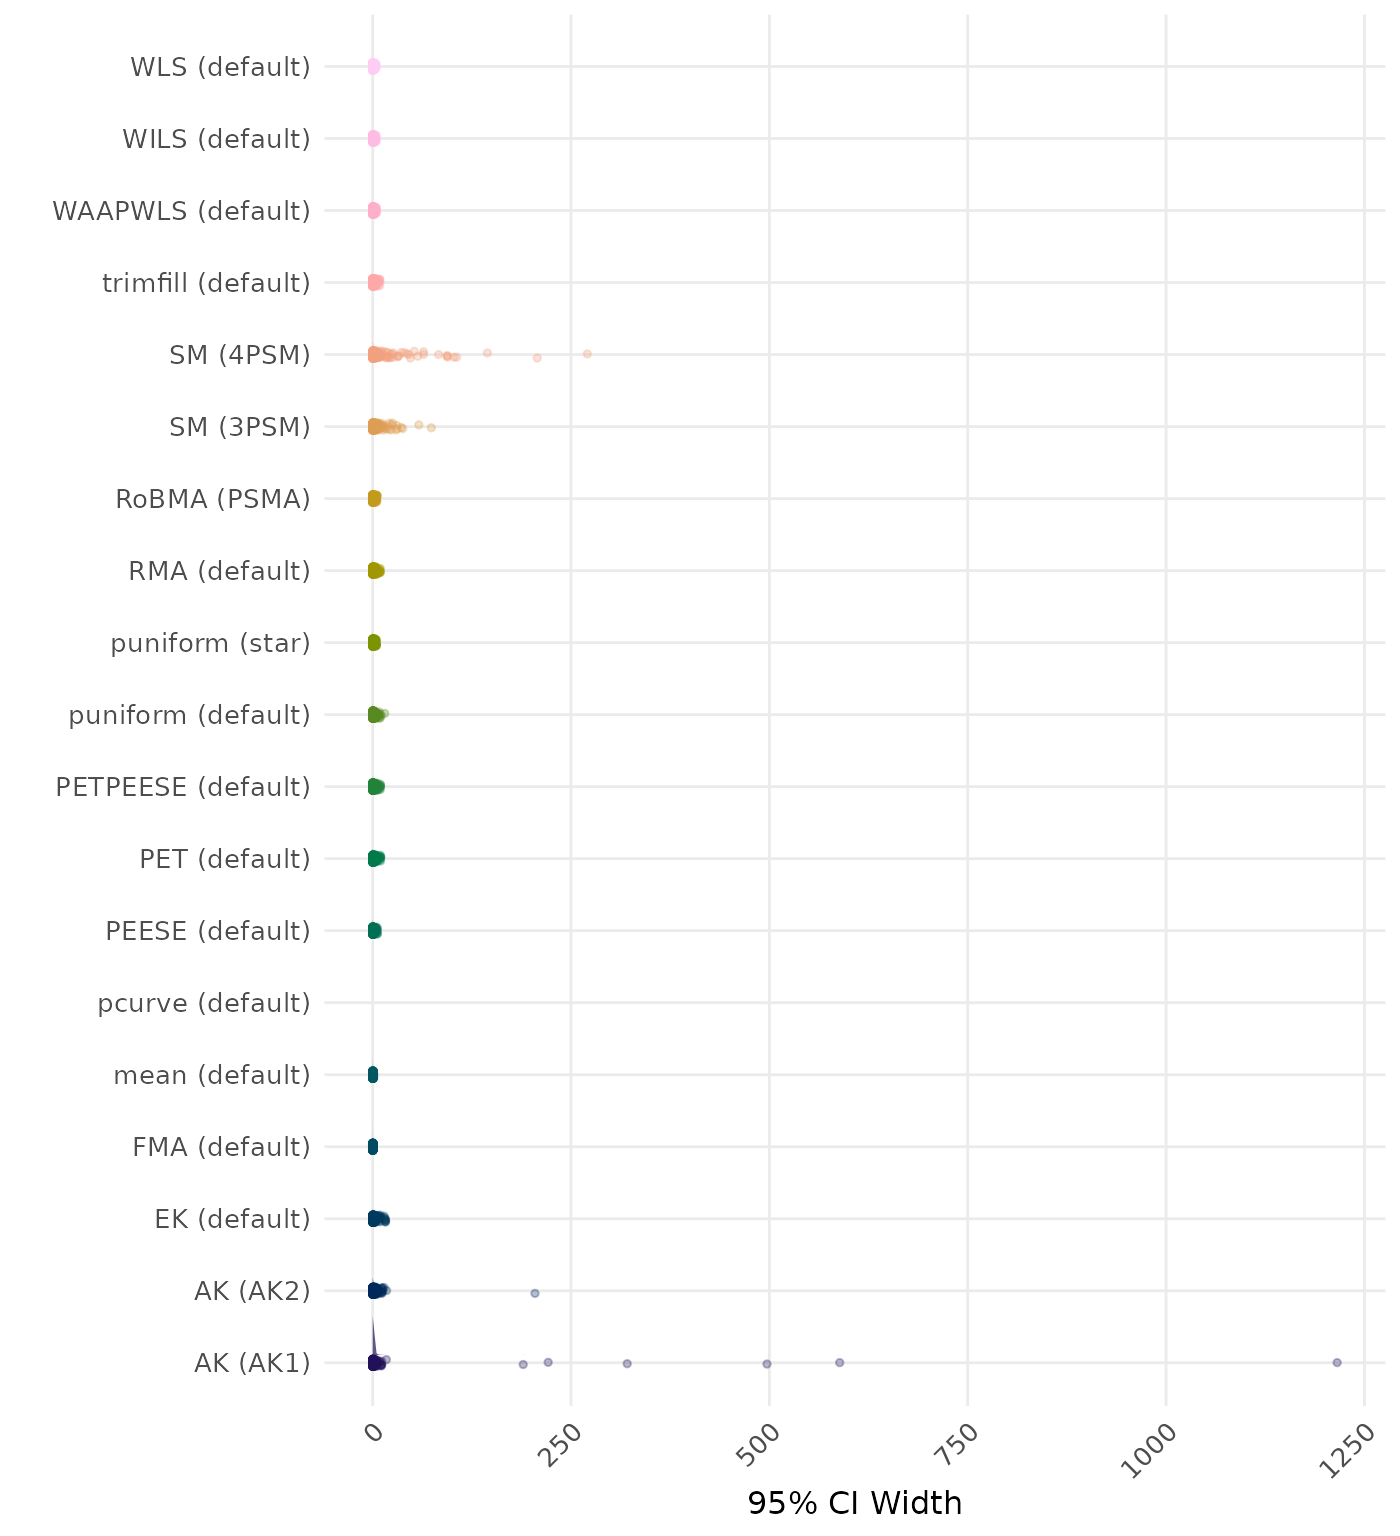
95% CI width is the average length of the 95% confidence interval for the true effect. A lower average 95% CI length indicates a better method.
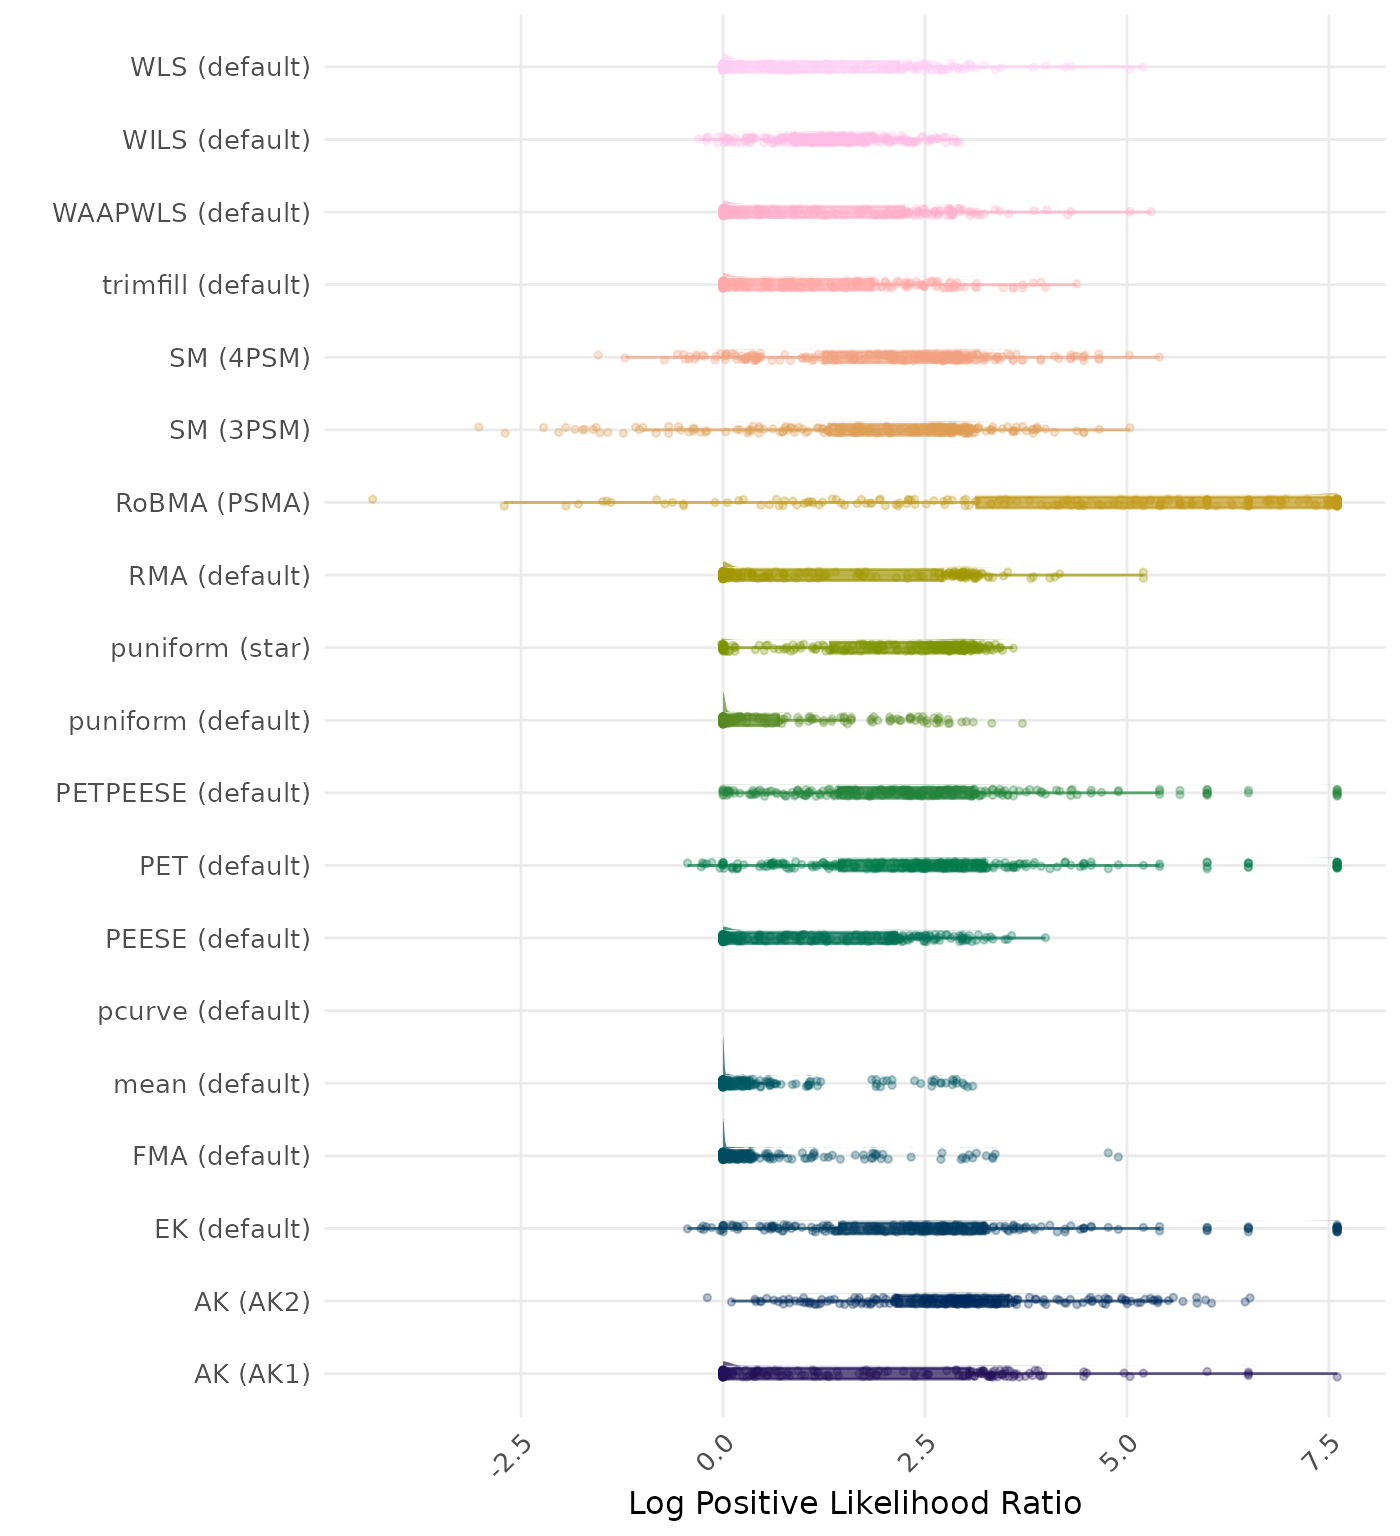
The positive likelihood ratio is an overall summary measure of hypothesis testing performance that combines power and type I error rate. It indicates how much a significant test result changes the odds of the alternative hypothesis versus the null hypothesis. A useful method has a positive likelihood ratio greater than 1 (or a log positive likelihood ratio greater than 0). A higher (log) positive likelihood ratio indicates a better method.
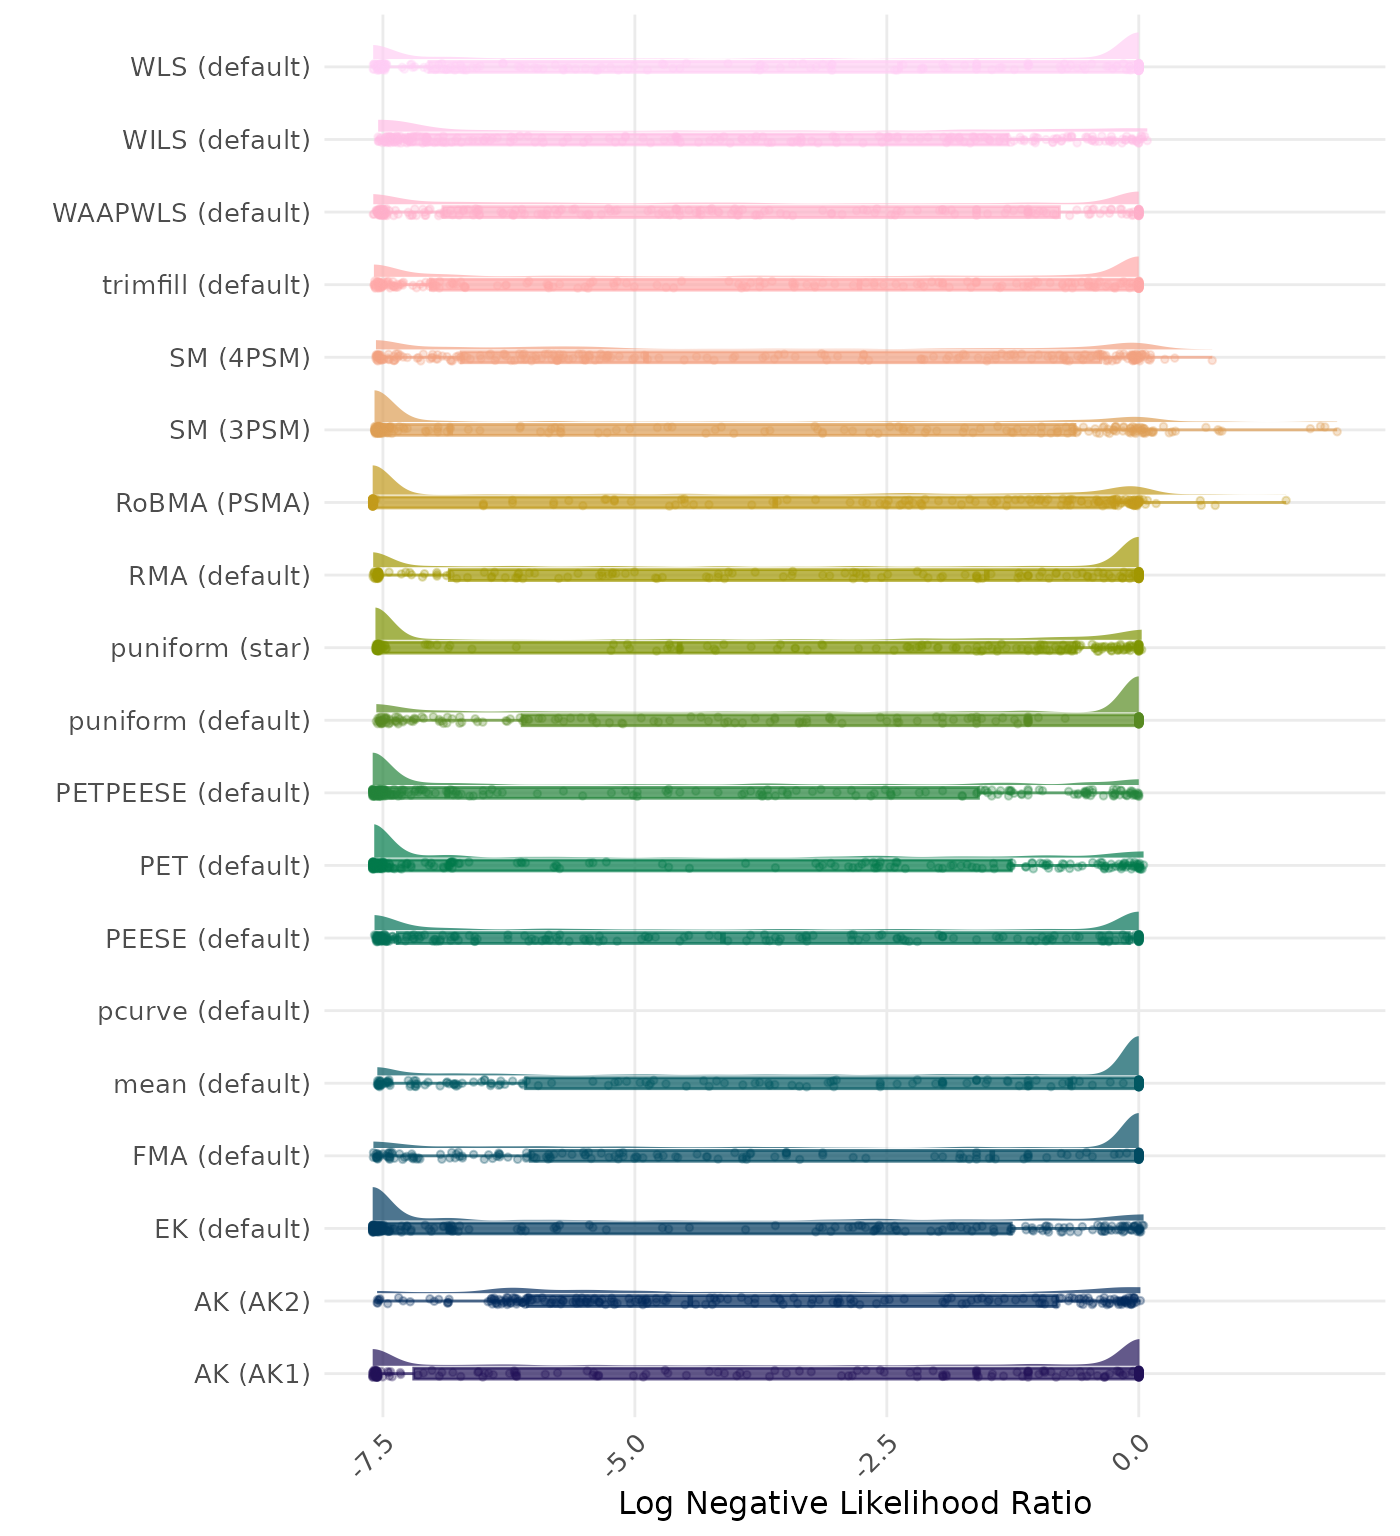
The negative likelihood ratio is an overall summary measure of hypothesis testing performance that combines power and type I error rate. It indicates how much a non-significant test result changes the odds of the alternative hypothesis versus the null hypothesis. A useful method has a negative likelihood ratio less than 1 (or a log negative likelihood ratio less than 0). A lower (log) negative likelihood ratio indicates a better method.
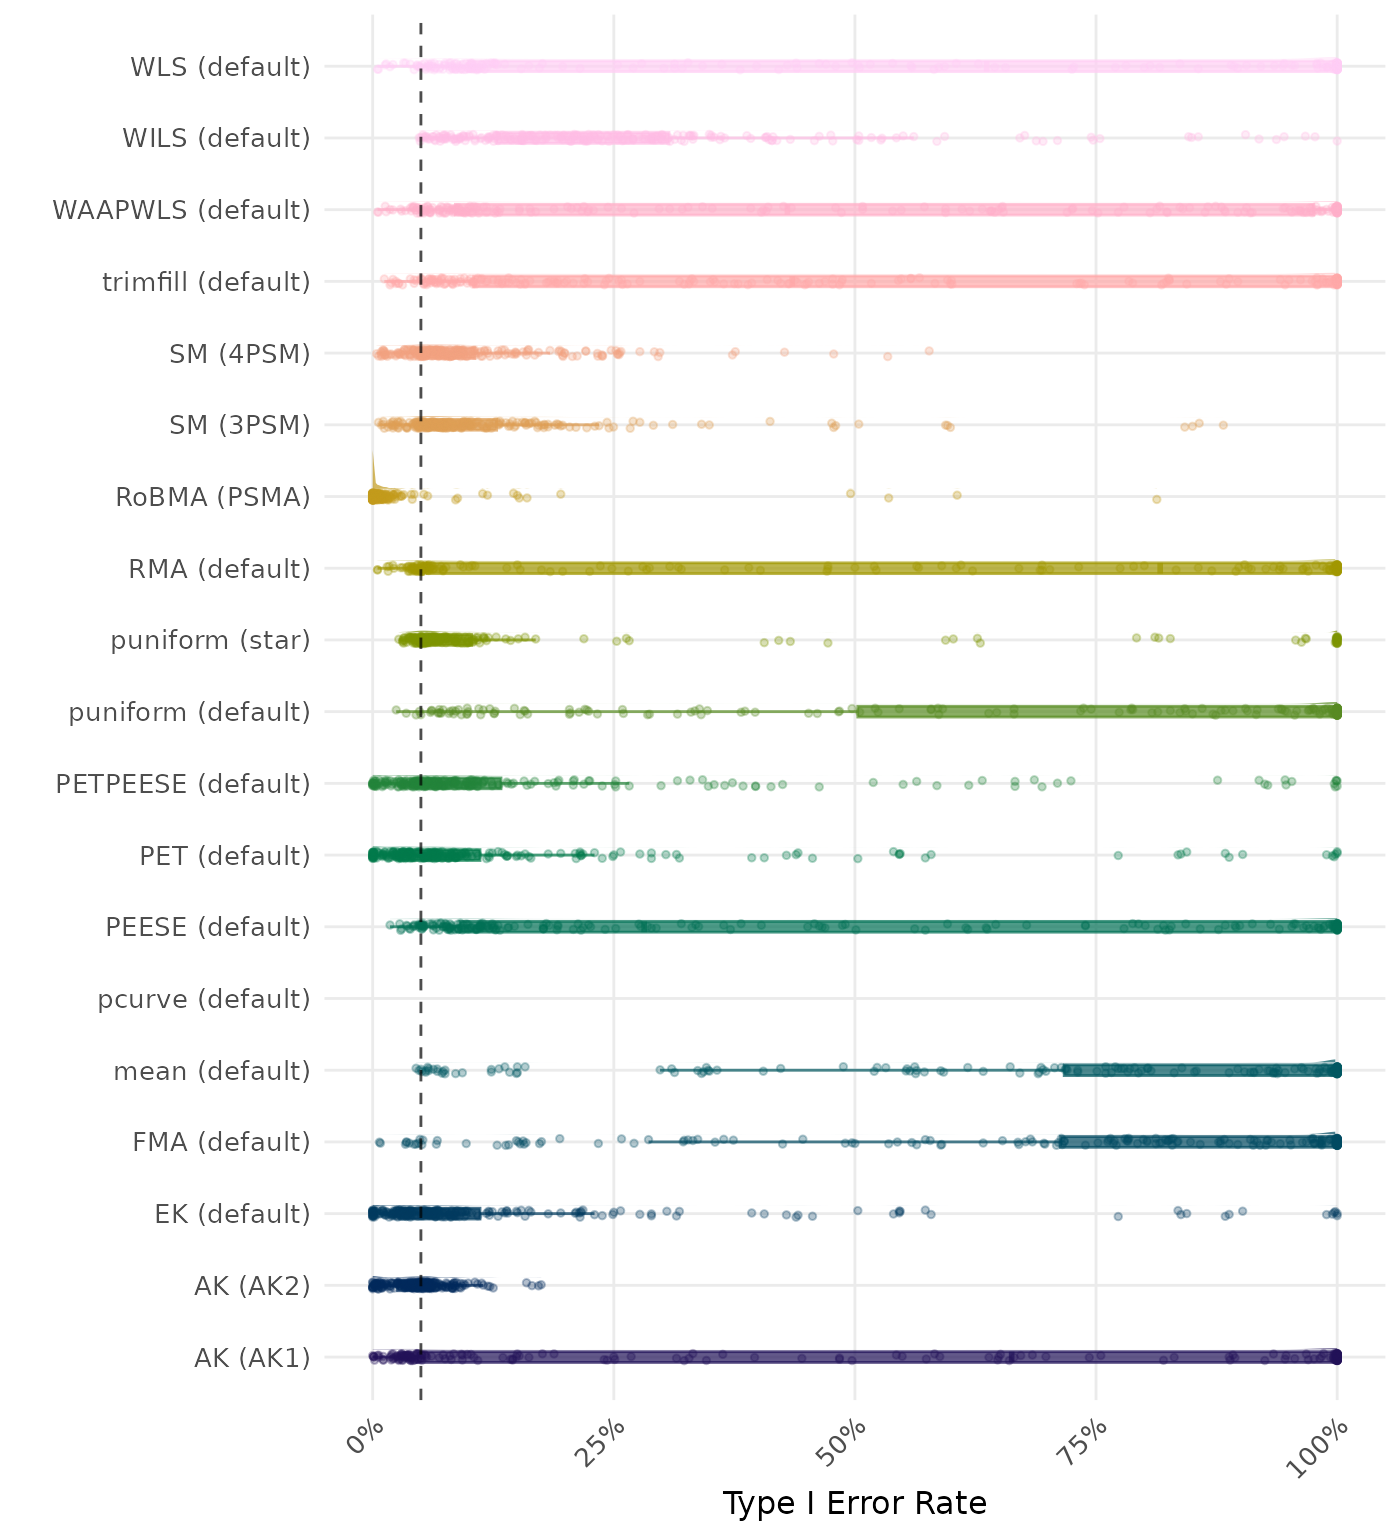
The type I error rate is the proportion of simulation runs in which the null hypothesis of no effect was incorrectly rejected when it was true. Ideally, this value should be close to the nominal level of 5%.
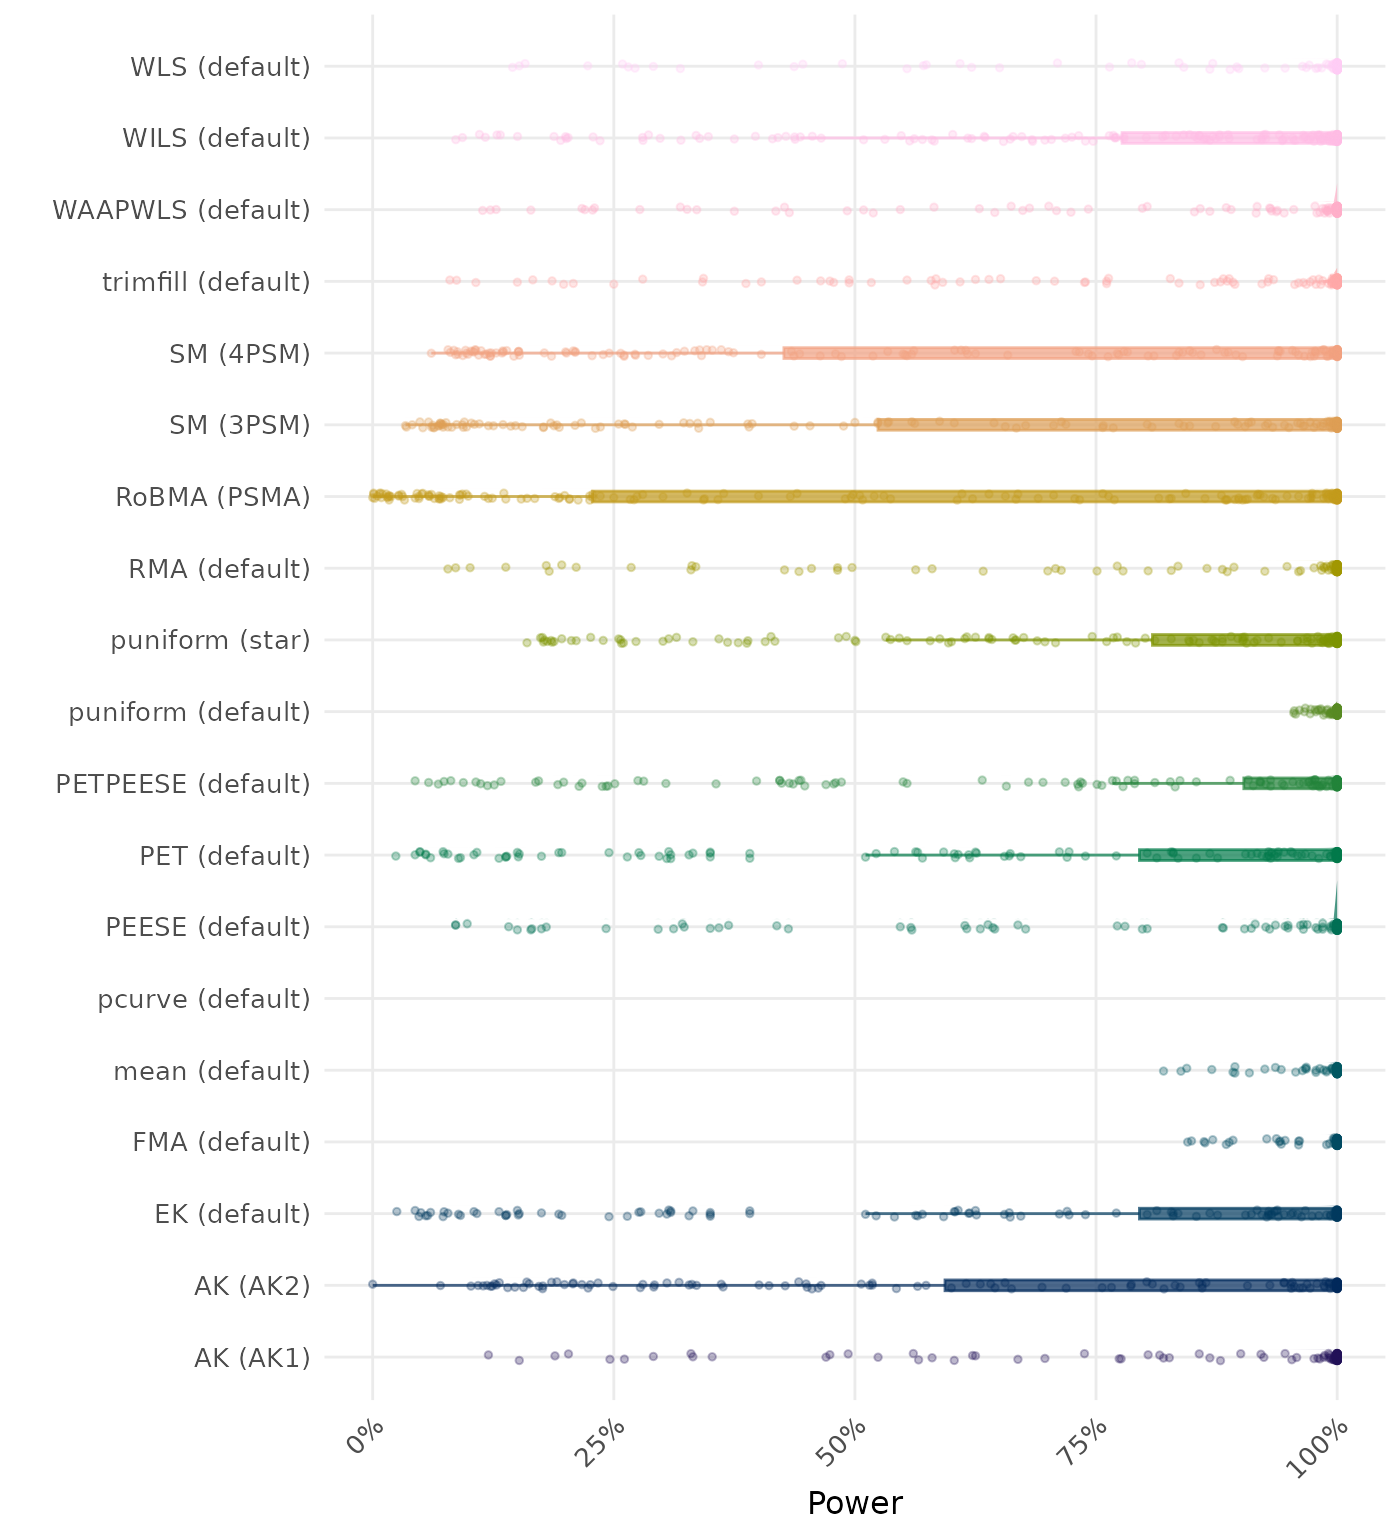
The power is the proportion of simulation runs in which the null hypothesis of no effect was correctly rejected when the alternative hypothesis was true. A higher power indicates a better method.
By-Condition Performance (Replacement in Case of Non-Convergence)
The results below incorporate method replacement to handle non-convergence. If a method fails to converge, its results are replaced with the results from a simpler method (e.g., random-effects meta-analysis without publication bias adjustment). This emulates what a data analyst may do in practice in case a method does not converge. However, note that these results do not correspond to “pure” method performance as they might combine multiple different methods. See Method Replacement Strategy for details of the method replacement specification.
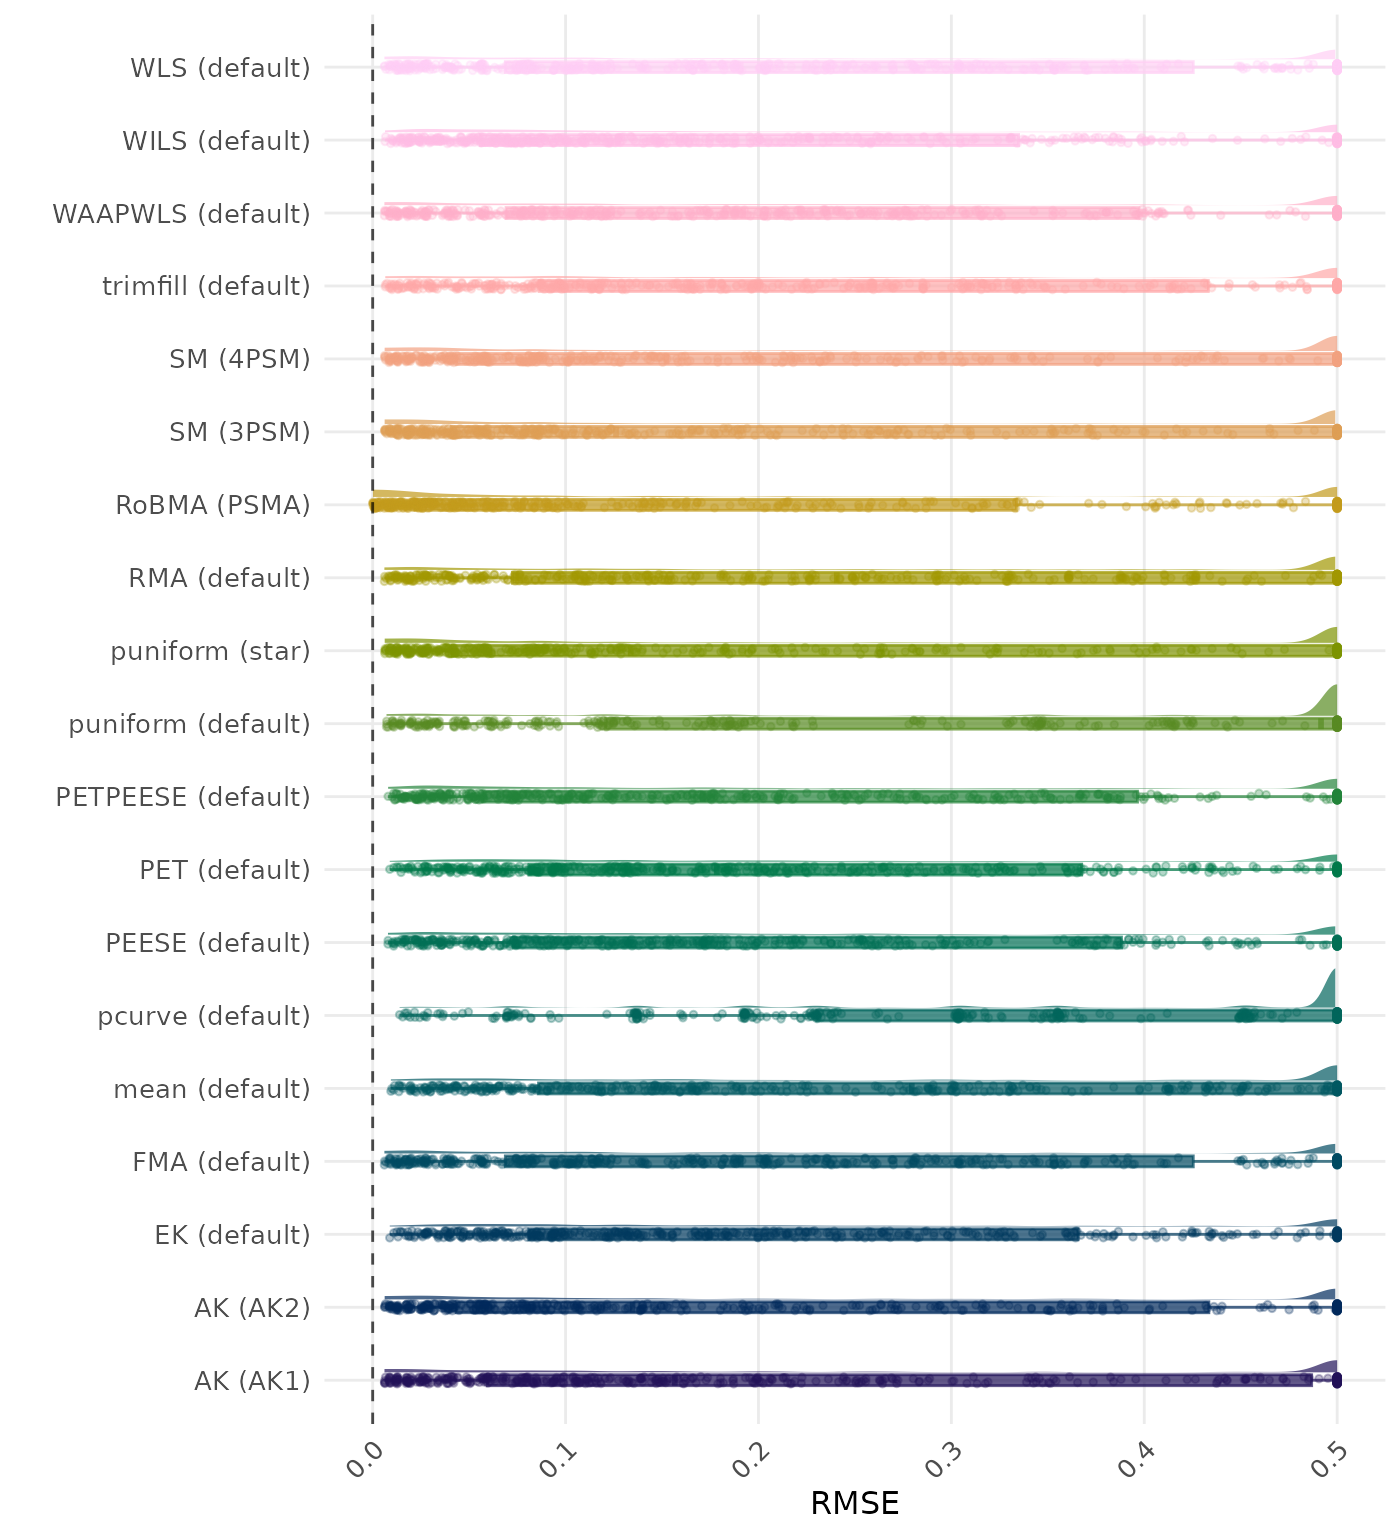
RMSE (Root Mean Square Error) is an overall summary measure of estimation performance that combines bias and empirical SE. RMSE is the square root of the average squared difference between the meta-analytic estimate and the true effect across simulation runs. A lower RMSE indicates a better method. Values larger than 0.5 are visualized as 0.5.
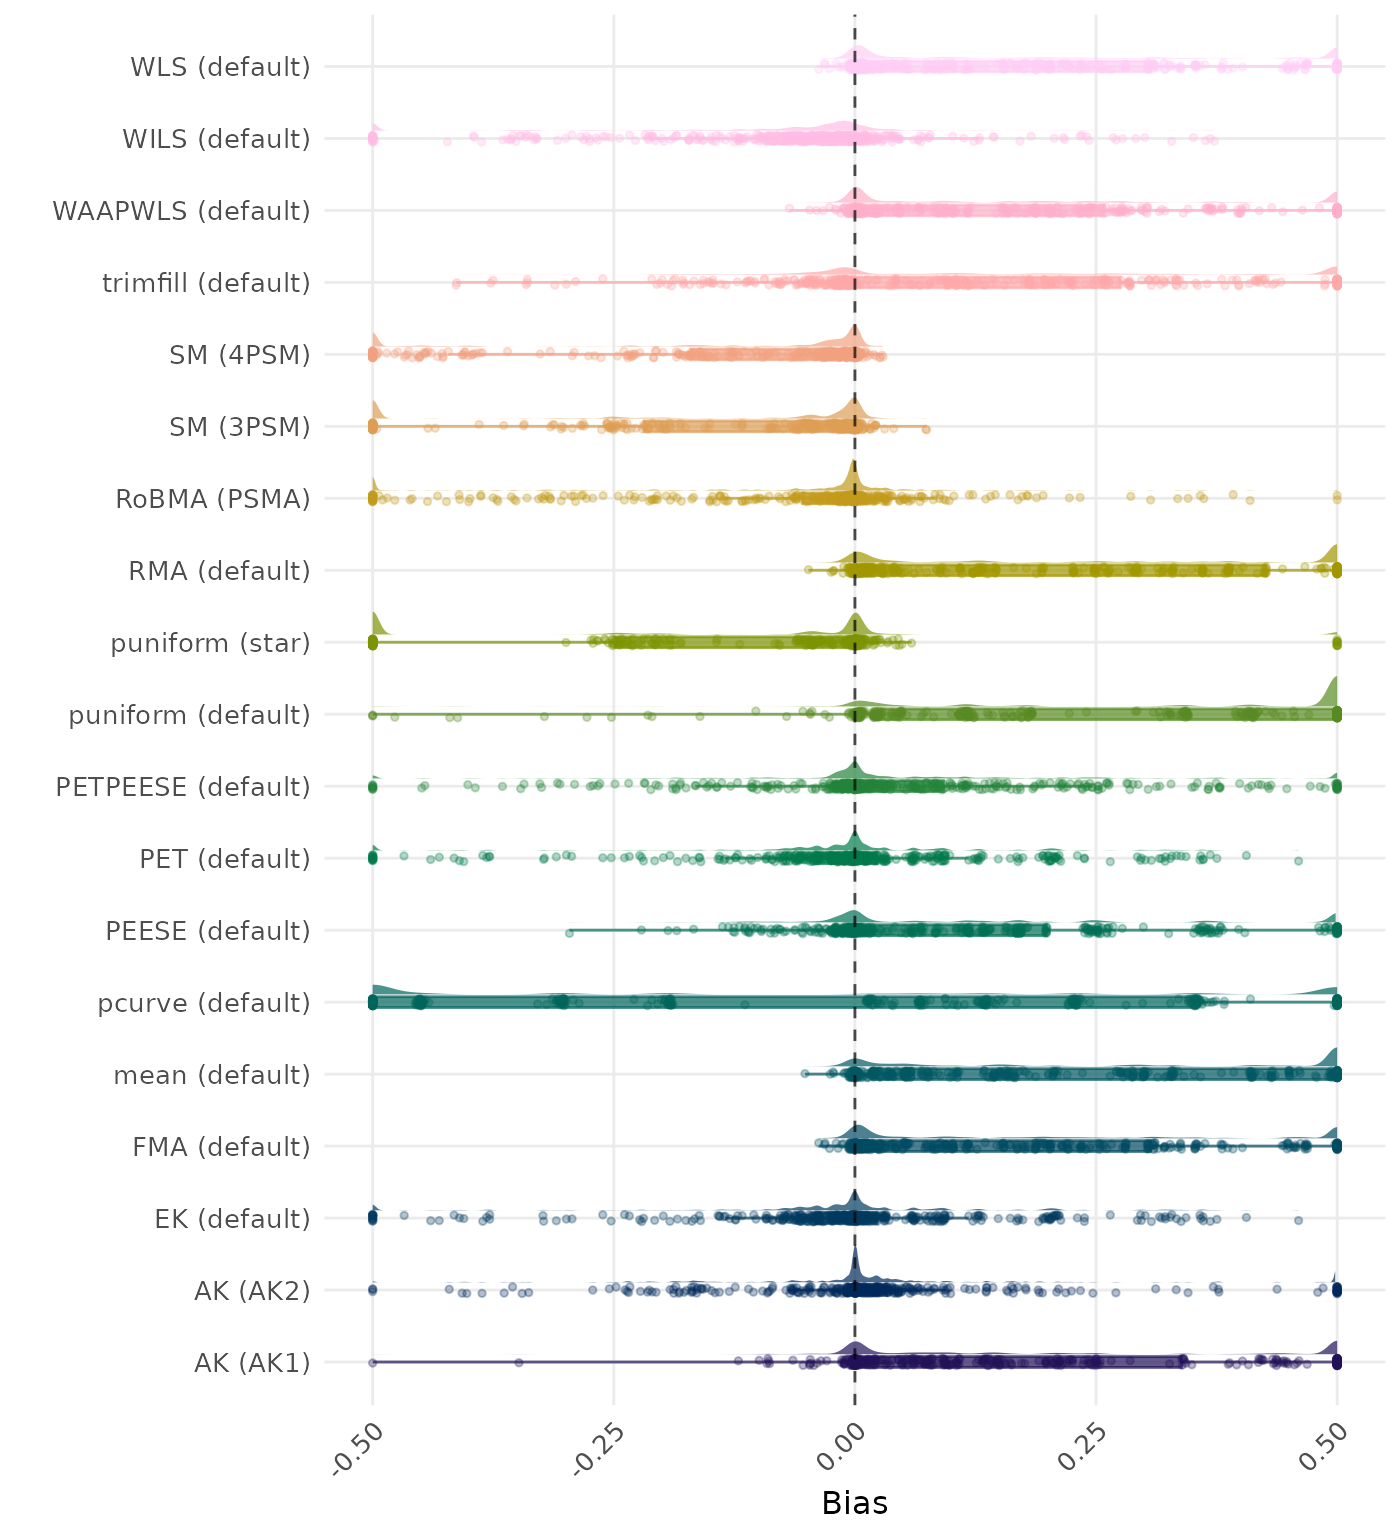
Bias is the average difference between the meta-analytic estimate and the true effect across simulation runs. Ideally, this value should be close to 0. Values lower than -0.5 or larger than 0.5 are visualized as -0.5 and 0.5 respectively.
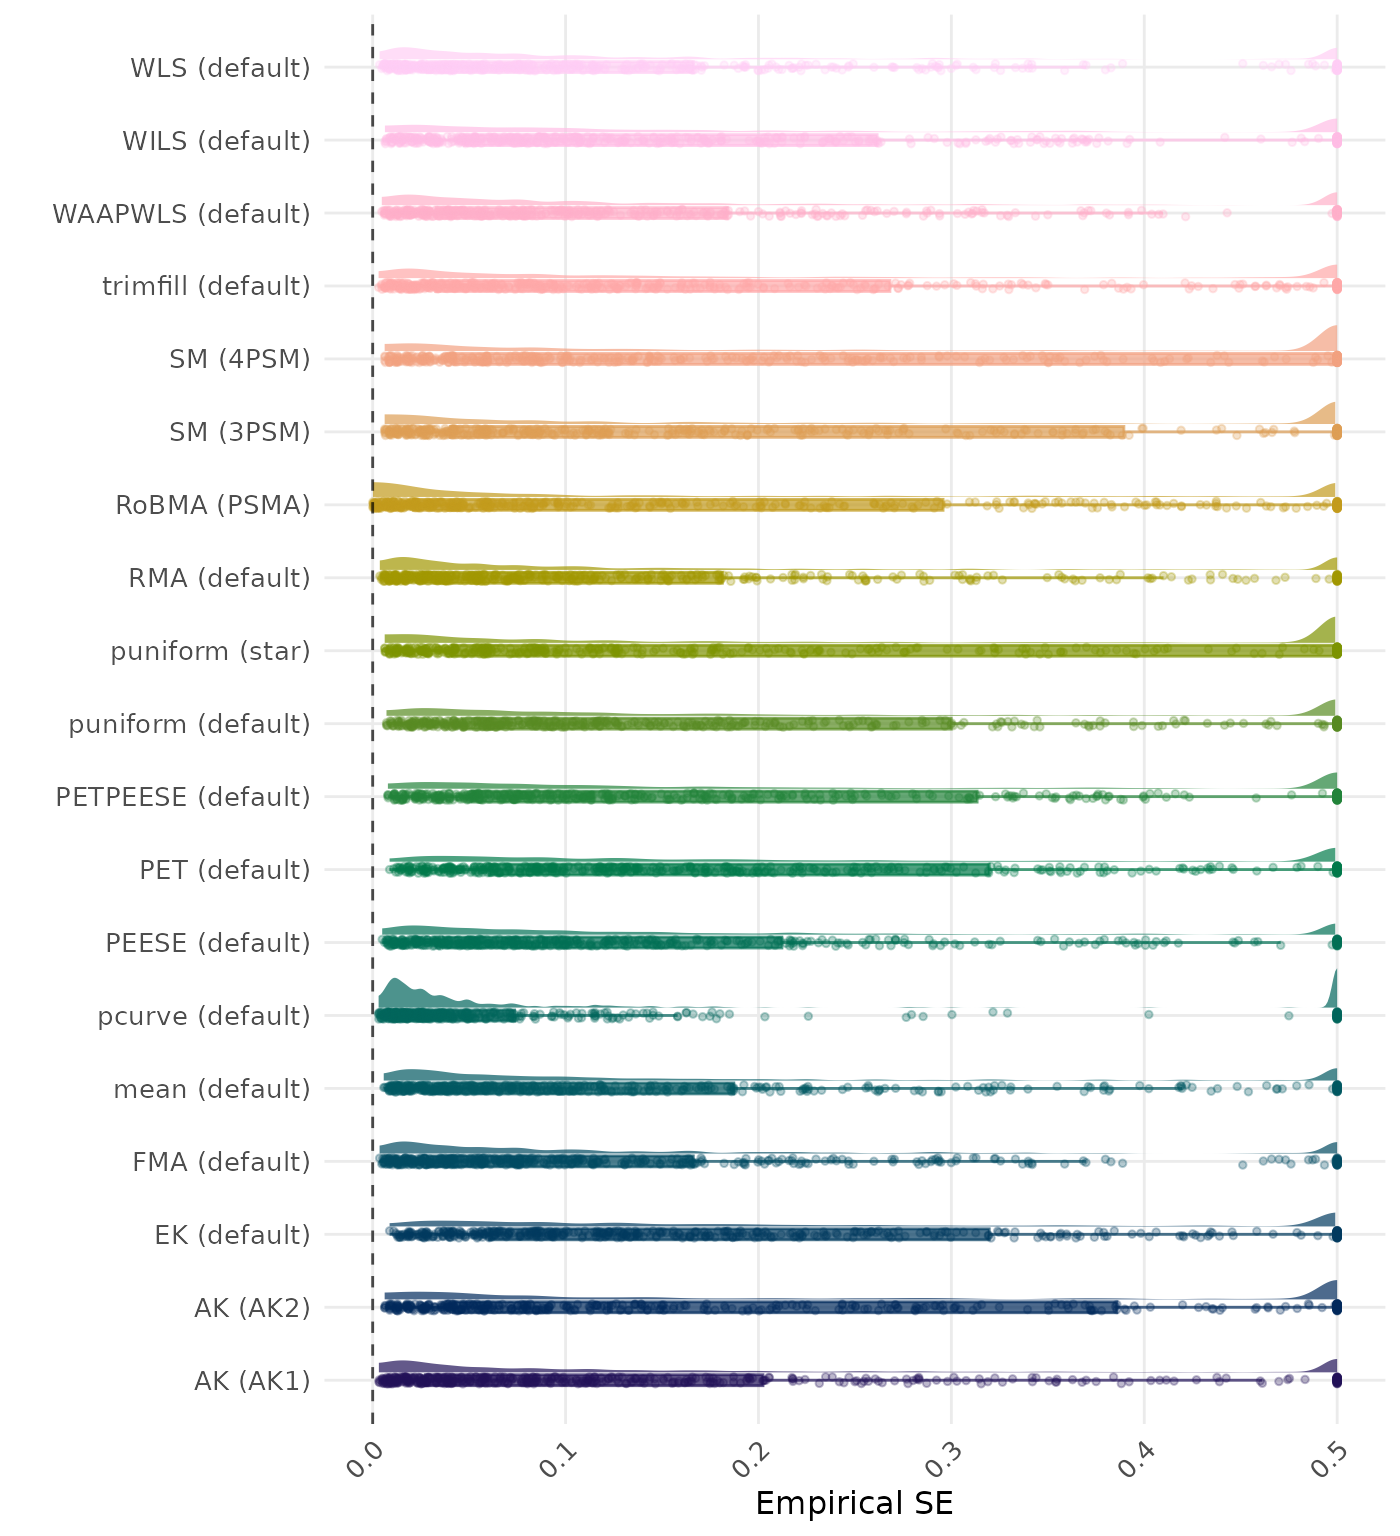
The empirical SE is the standard deviation of the meta-analytic estimate across simulation runs. A lower empirical SE indicates less variability and better method performance. Values larger than 0.5 are visualized as 0.5.
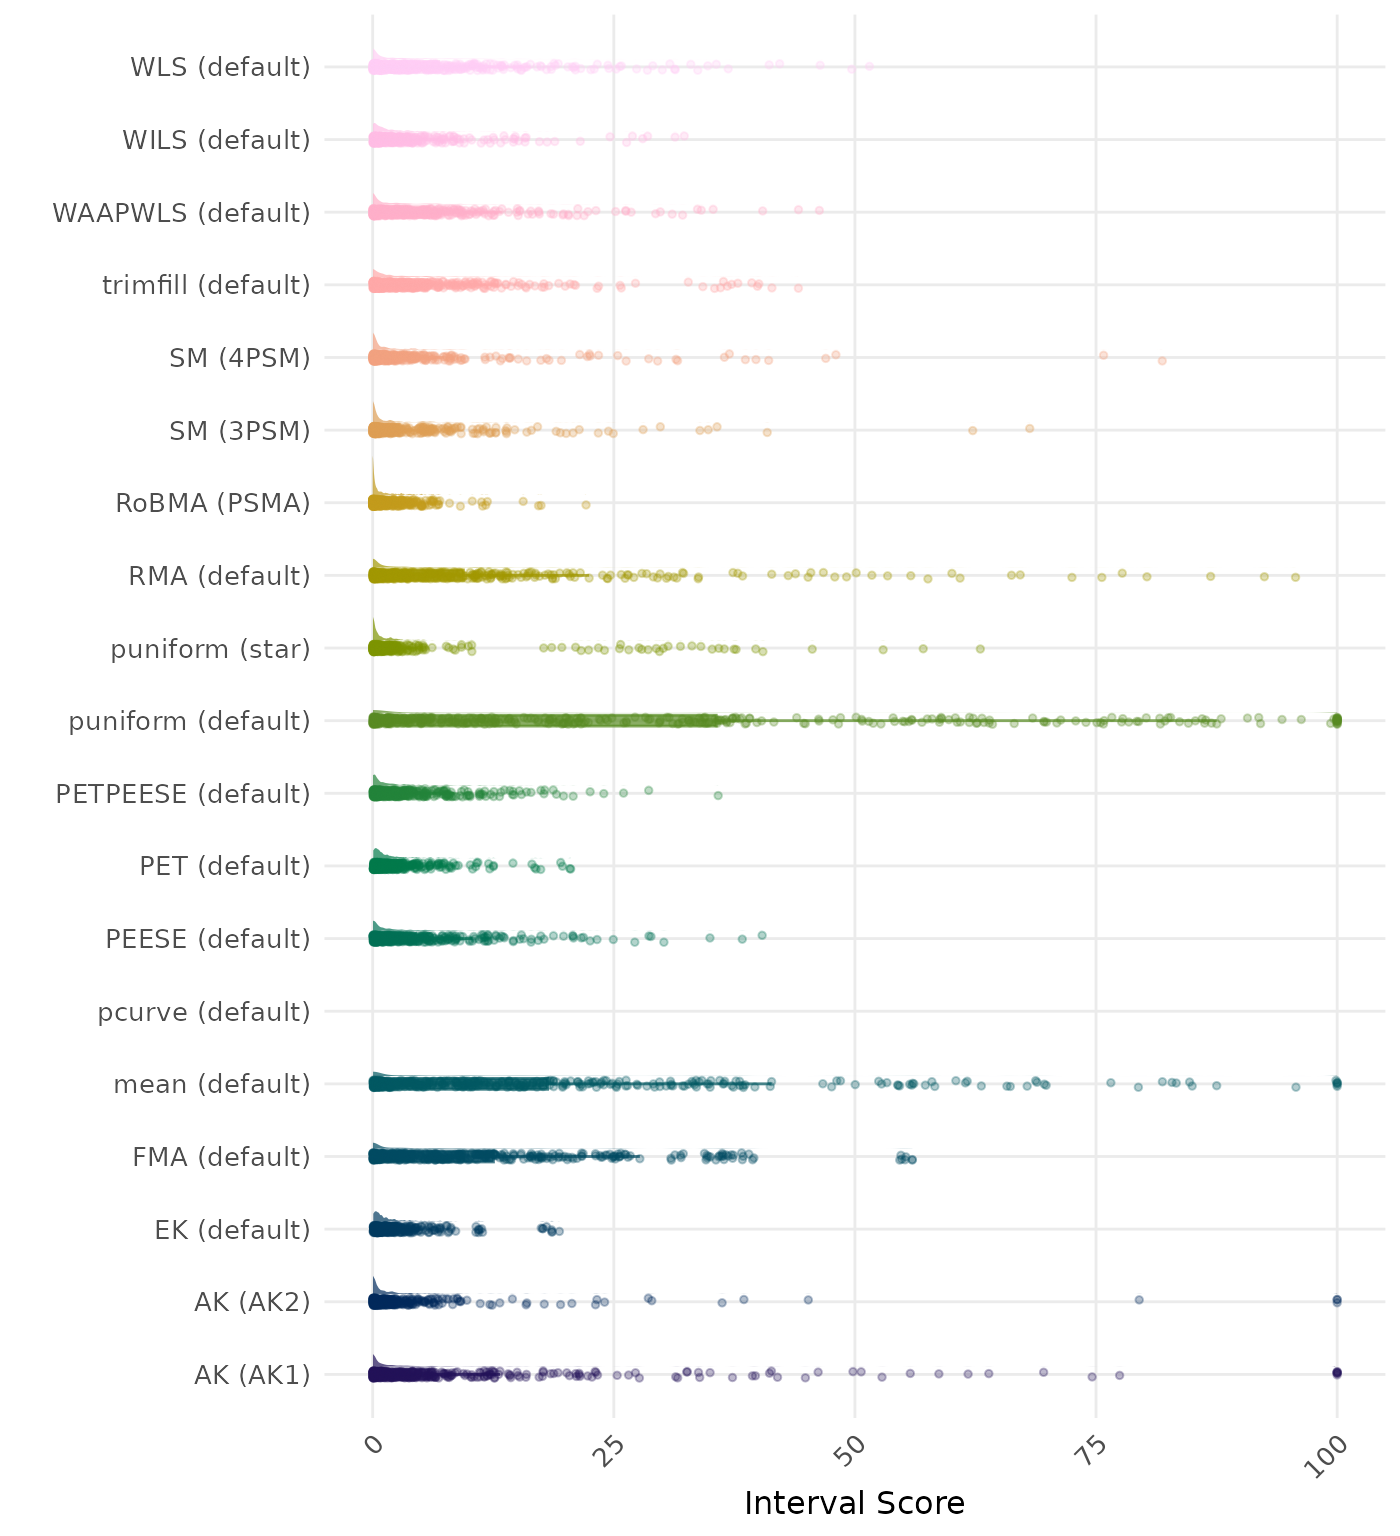
The interval score measures the accuracy of a confidence interval by combining its width and coverage. It penalizes intervals that are too wide or that fail to include the true value. A lower interval score indicates a better method. Values larger than 100 are visualized as 100.
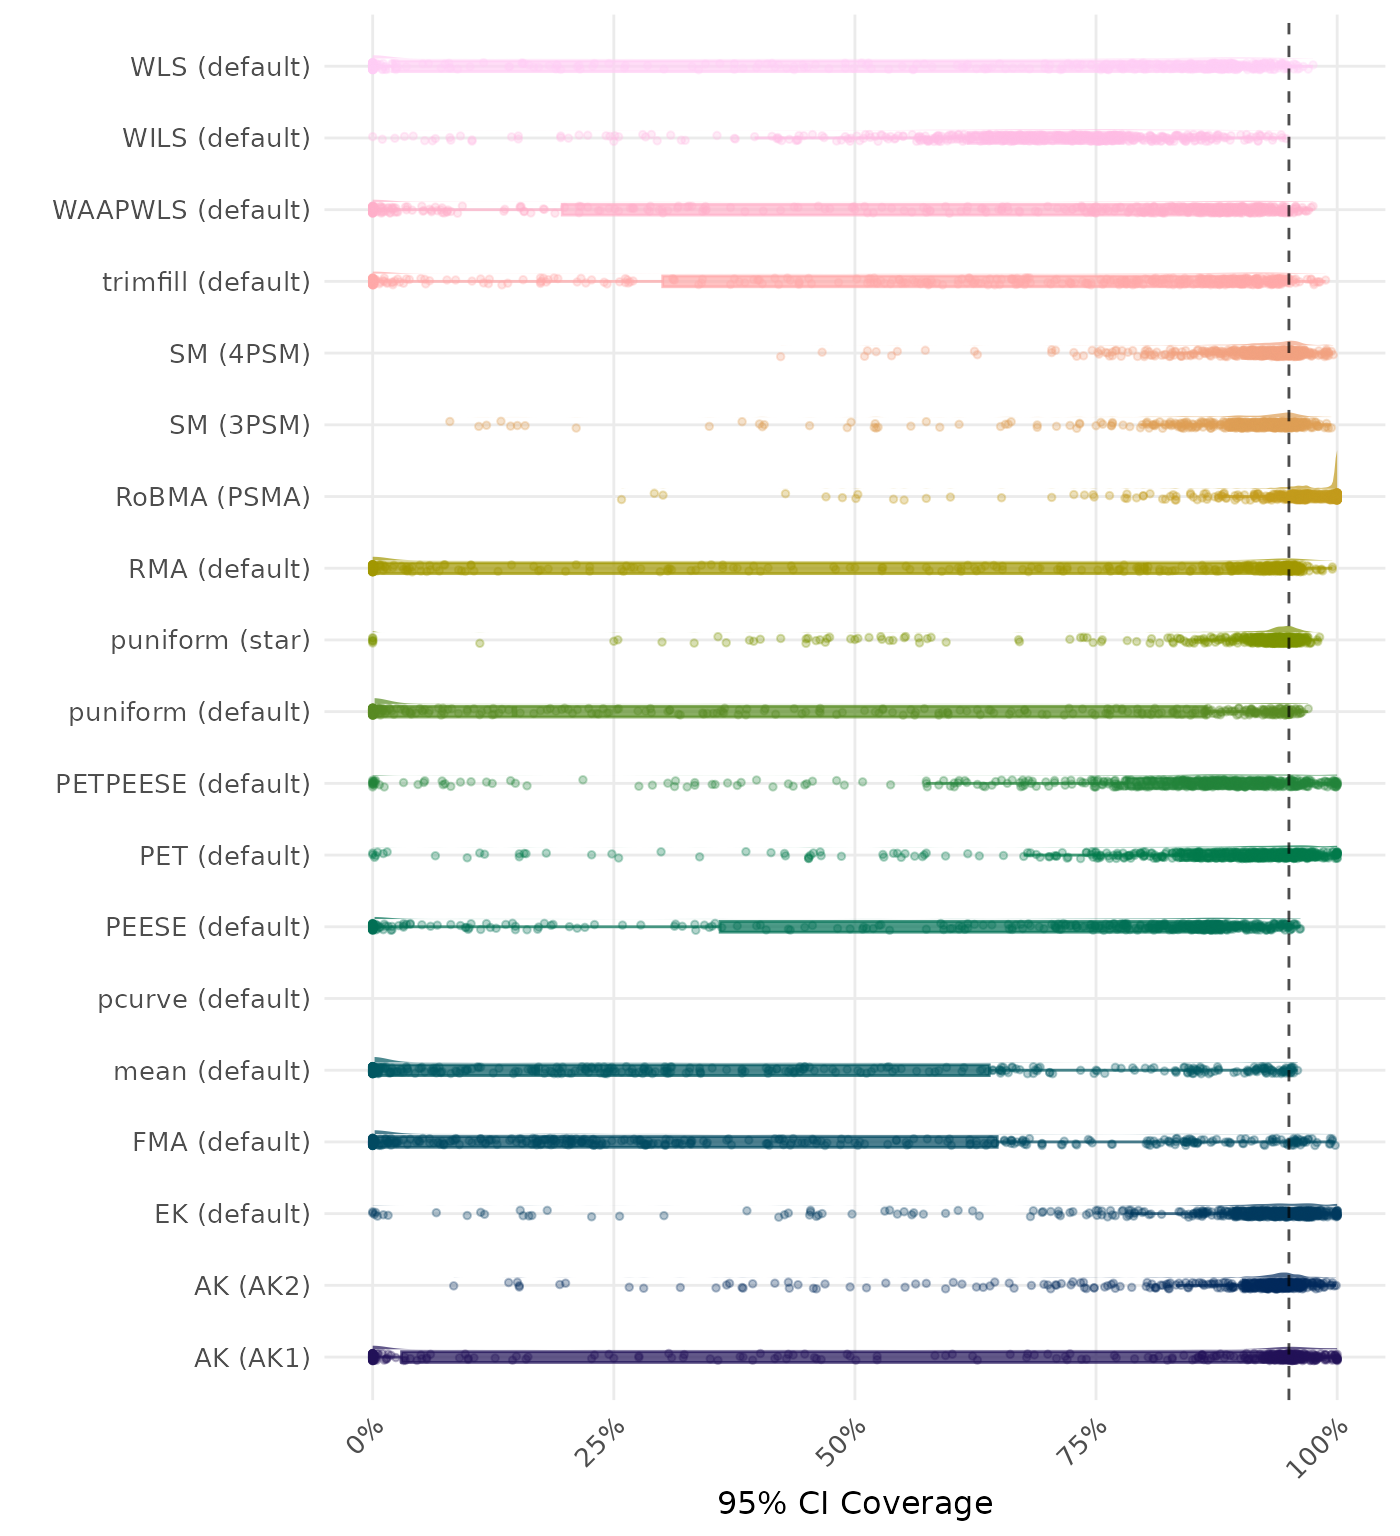
95% CI coverage is the proportion of simulation runs in which the 95% confidence interval contained the true effect. Ideally, this value should be close to the nominal level of 95%.
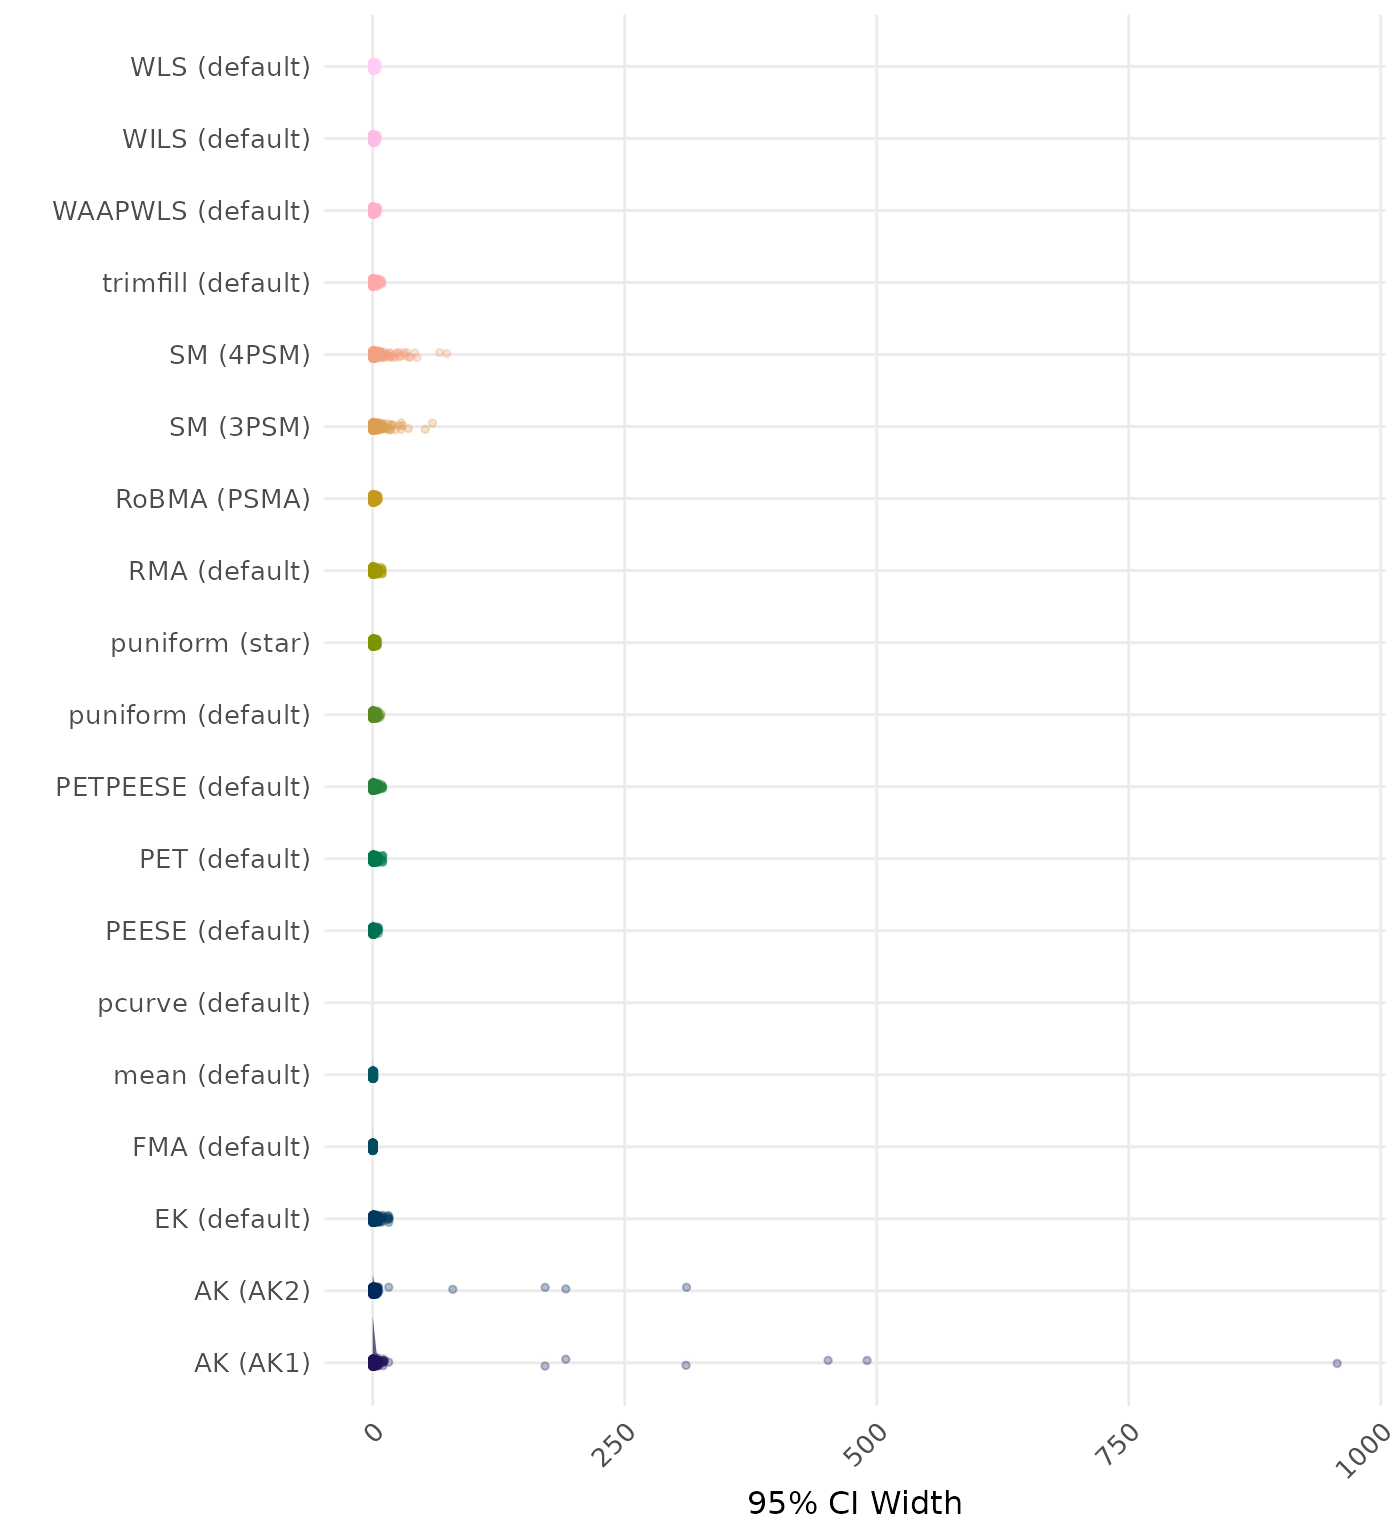
95% CI width is the average length of the 95% confidence interval for the true effect. A lower average 95% CI length indicates a better method.
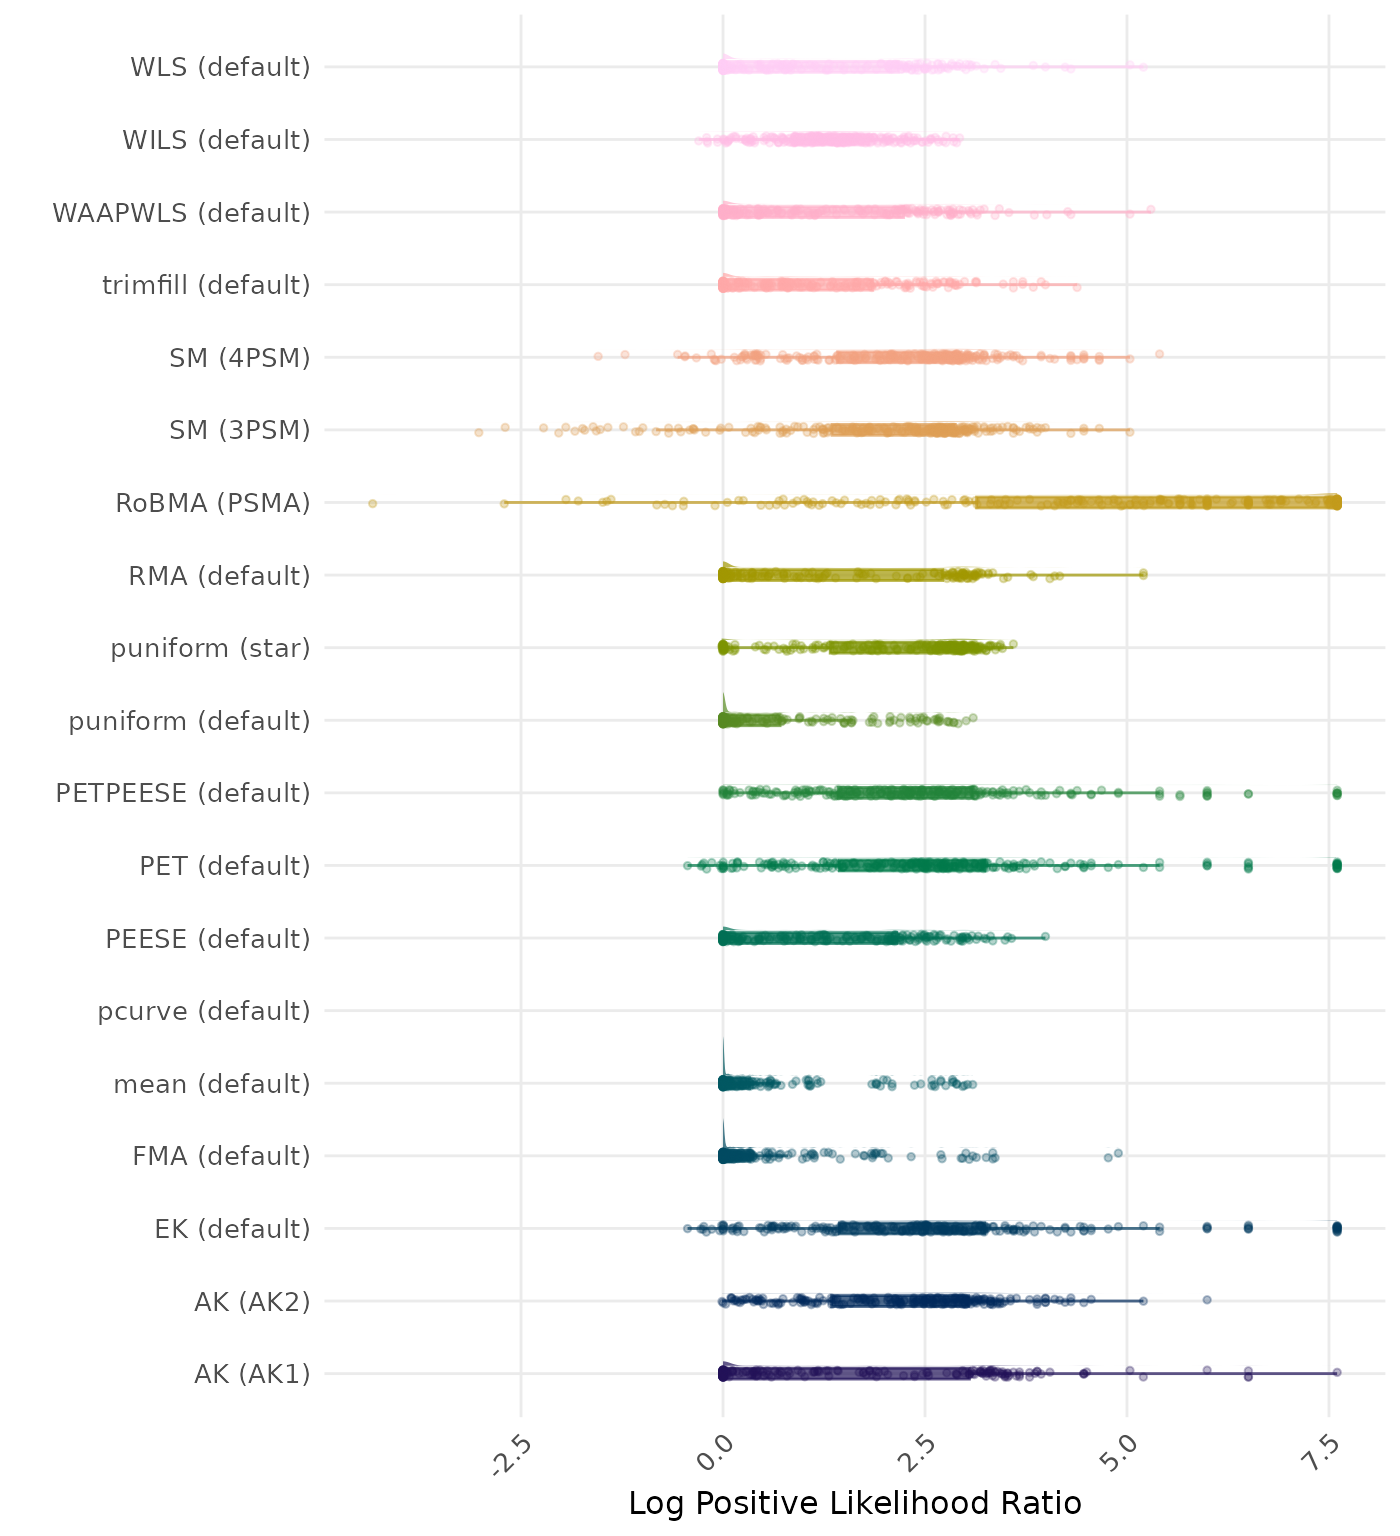
The positive likelihood ratio is an overall summary measure of hypothesis testing performance that combines power and type I error rate. It indicates how much a significant test result changes the odds of the alternative hypothesis versus the null hypothesis. A useful method has a positive likelihood ratio greater than 1 (or a log positive likelihood ratio greater than 0). A higher (log) positive likelihood ratio indicates a better method.
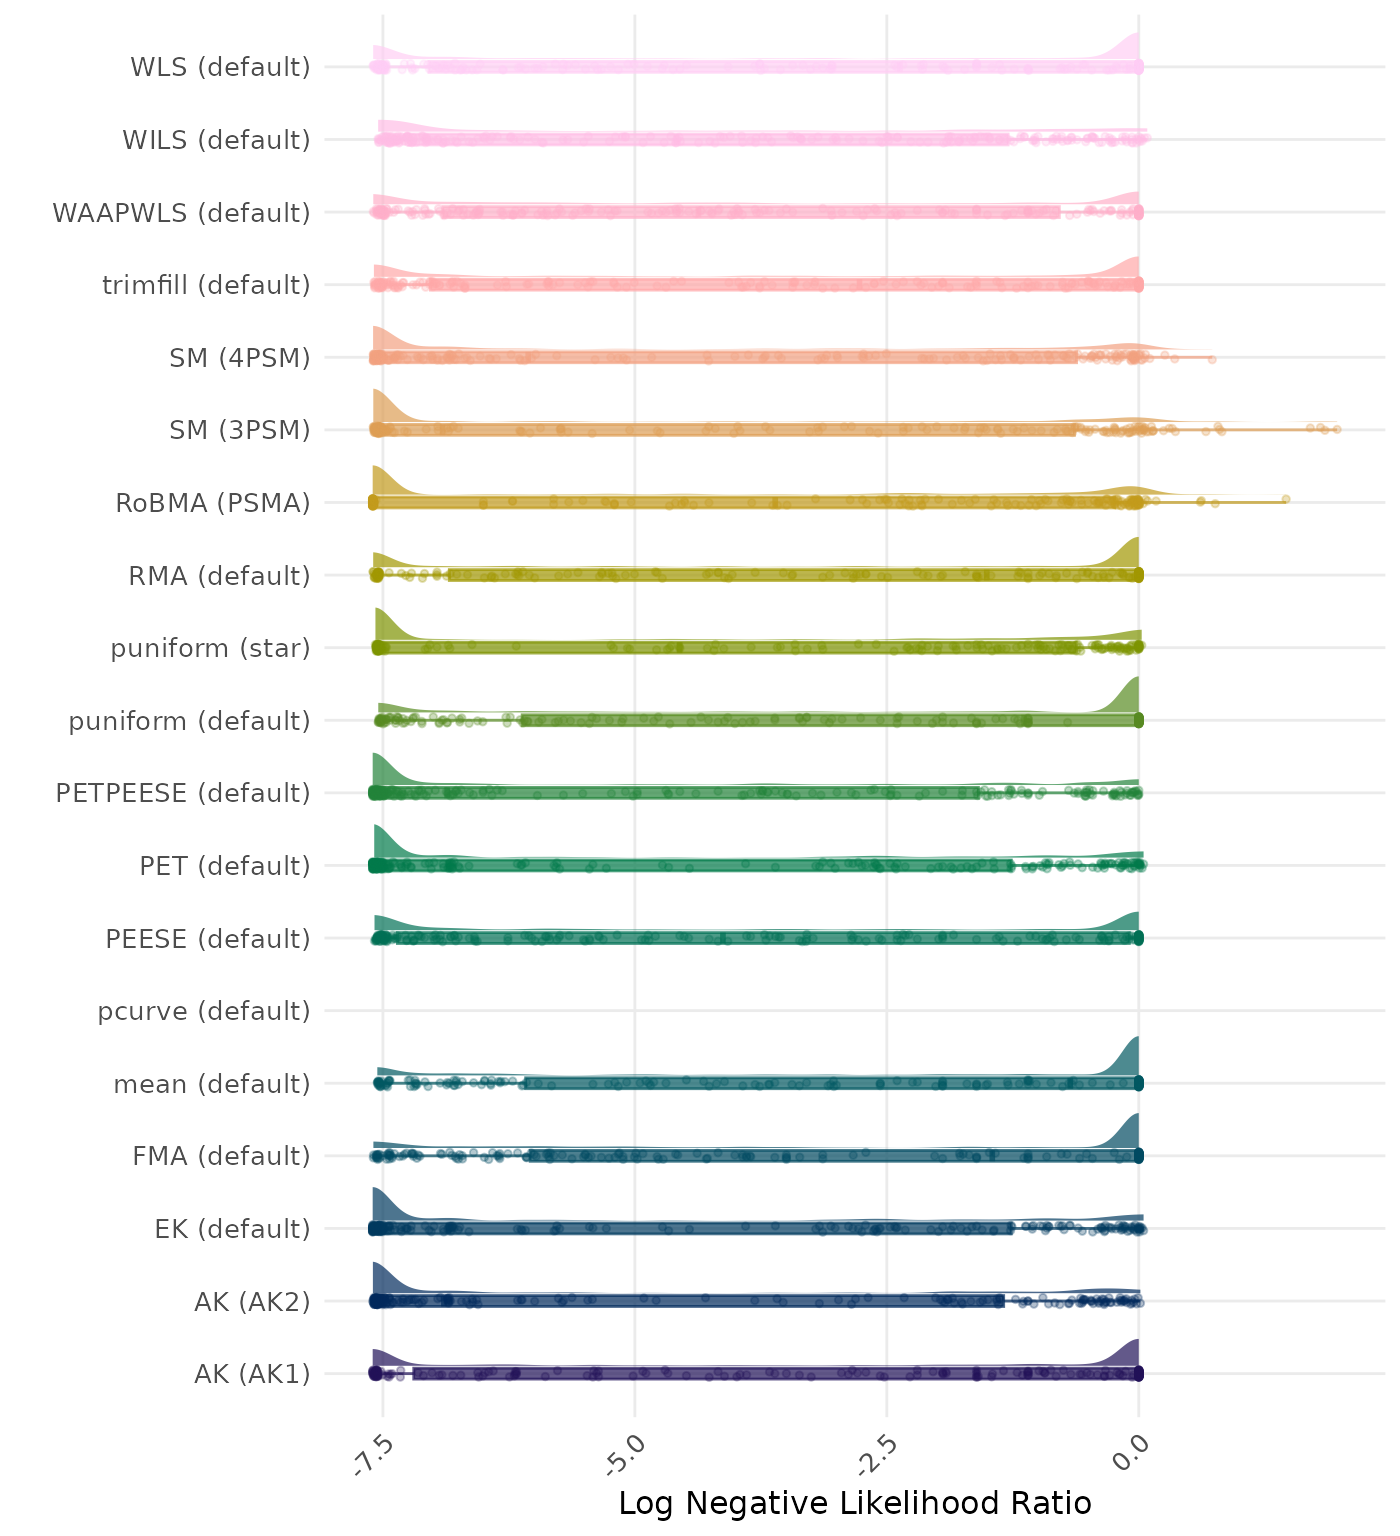
The negative likelihood ratio is an overall summary measure of hypothesis testing performance that combines power and type I error rate. It indicates how much a non-significant test result changes the odds of the alternative hypothesis versus the null hypothesis. A useful method has a negative likelihood ratio less than 1 (or a log negative likelihood ratio less than 0). A lower (log) negative likelihood ratio indicates a better method.
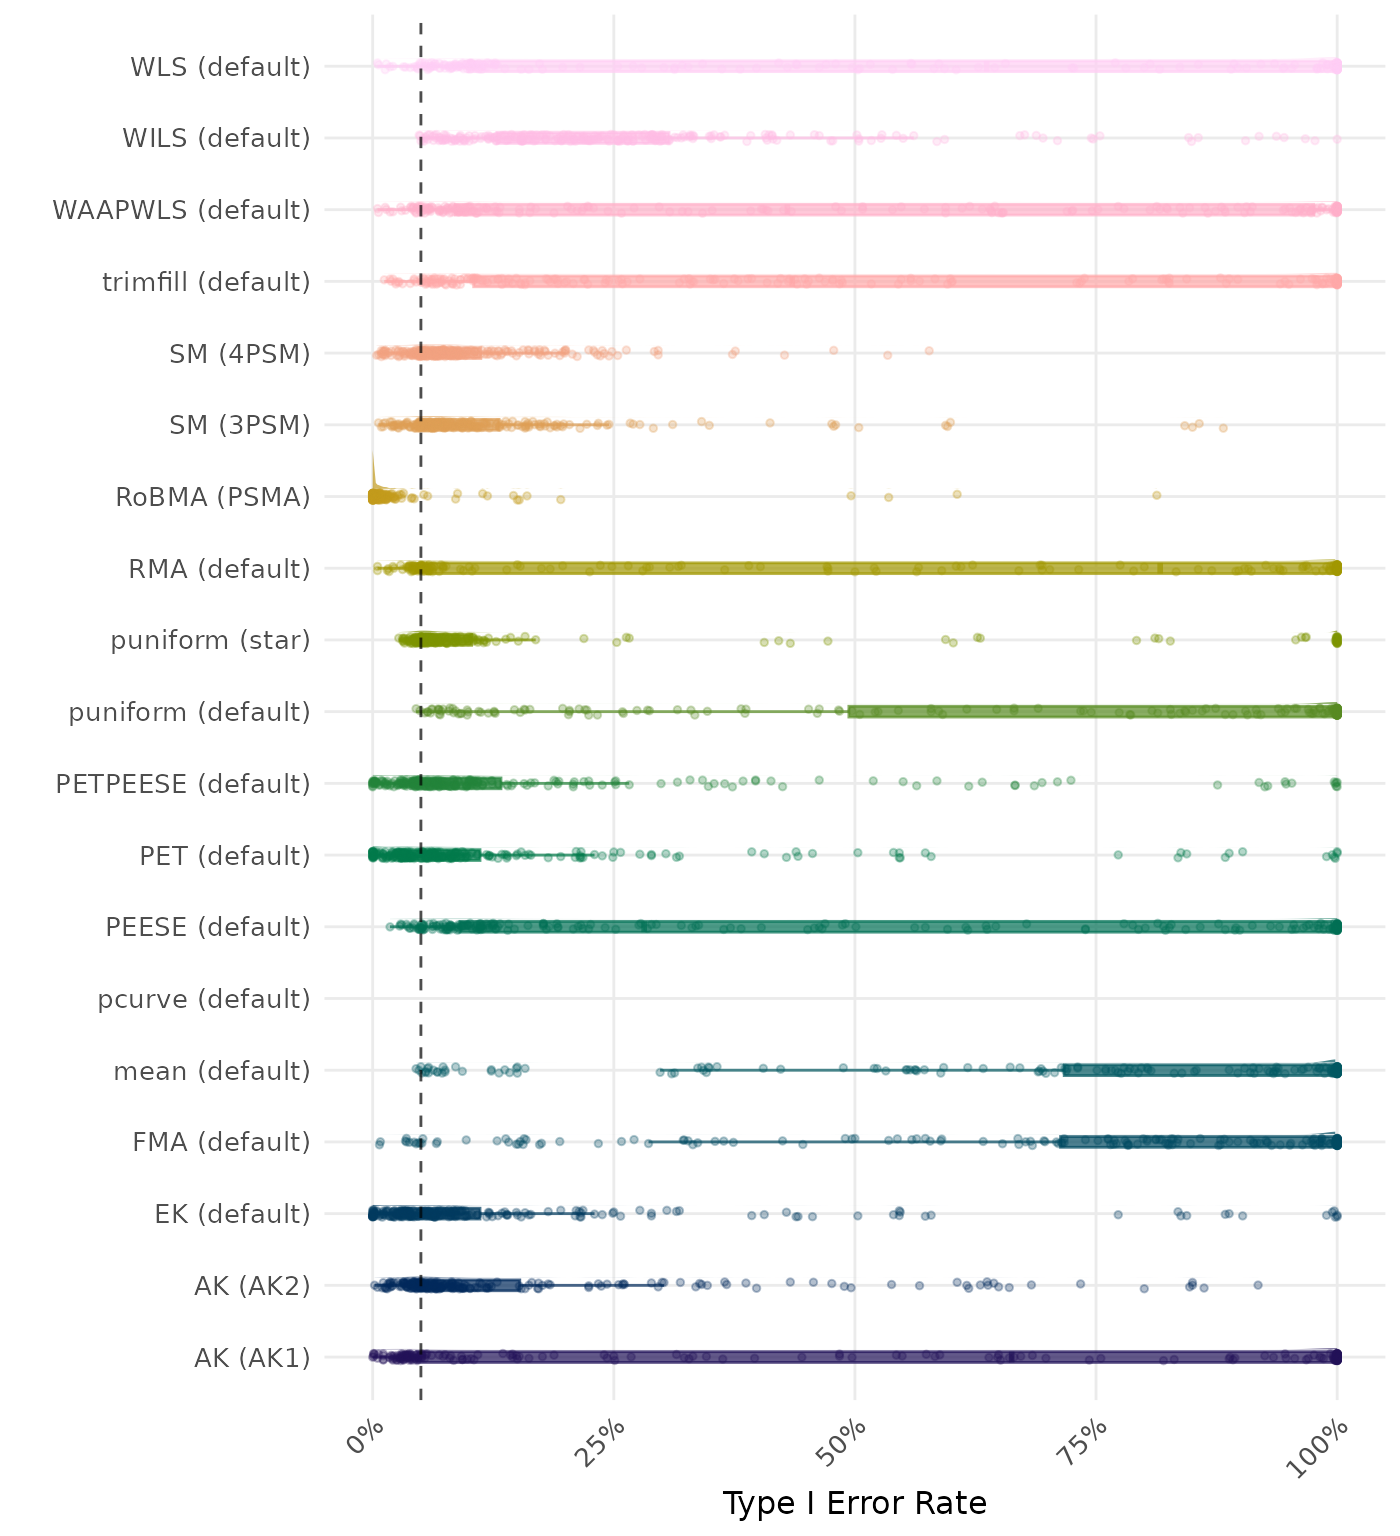
The type I error rate is the proportion of simulation runs in which the null hypothesis of no effect was incorrectly rejected when it was true. Ideally, this value should be close to the nominal level of 5%.
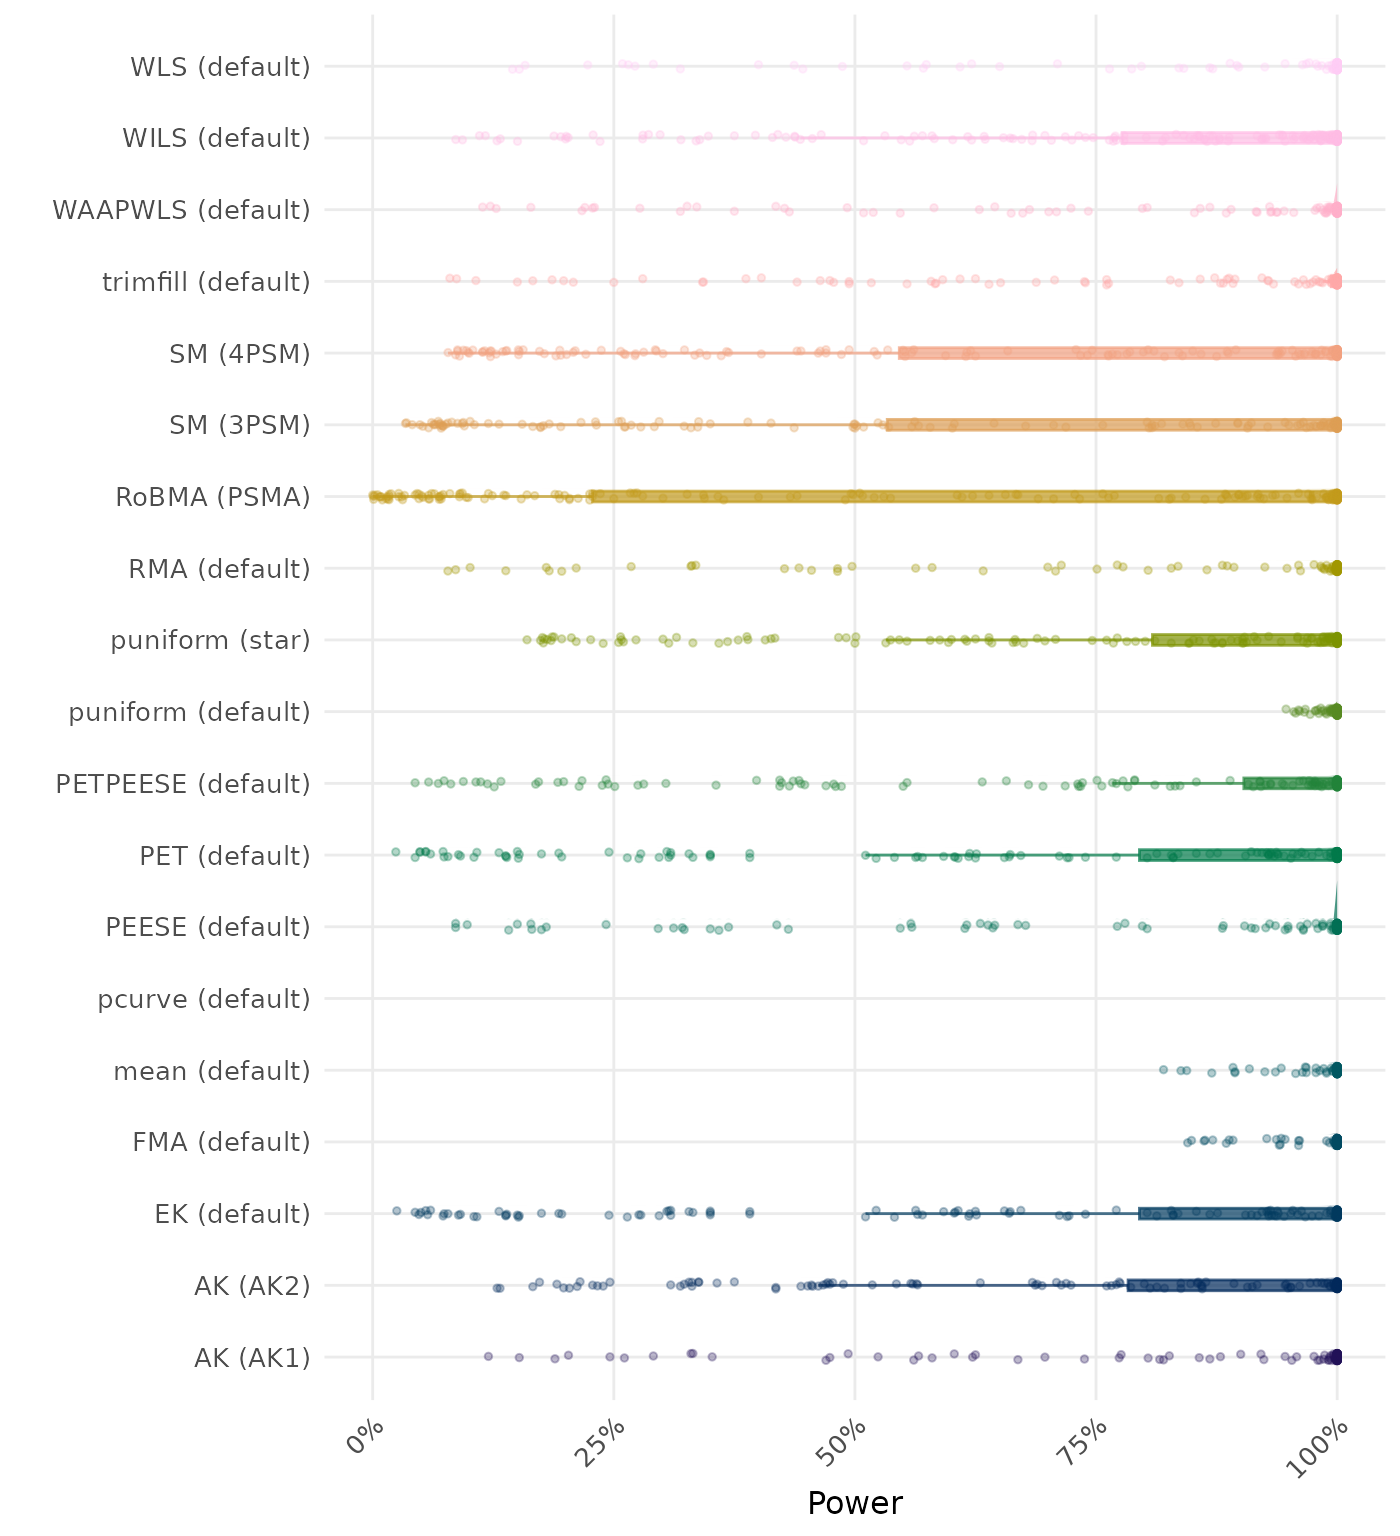
The power is the proportion of simulation runs in which the null hypothesis of no effect was correctly rejected when the alternative hypothesis was true. A higher power indicates a better method.
Session Info
This report was compiled on Wed Sep 30 15:41:09 2026 (UTC) using the following computational environment
## R version 4.6.1 (2026-06-24)
## Platform: x86_64-pc-linux-gnu
## Running under: Ubuntu 24.04.5 LTS
##
## Matrix products: default
## BLAS:   /usr/lib/x86_64-linux-gnu/openblas-pthread/libblas.so.3
## LAPACK: /usr/lib/x86_64-linux-gnu/openblas-pthread/libopenblasp-r0.3.26.so;  LAPACK version 3.12.0
##
## locale:
##  [1] LC_CTYPE=C.UTF-8       LC_NUMERIC=C           LC_TIME=C.UTF-8
##  [4] LC_COLLATE=C.UTF-8     LC_MONETARY=C.UTF-8    LC_MESSAGES=C.UTF-8
##  [7] LC_PAPER=C.UTF-8       LC_NAME=C              LC_ADDRESS=C
## [10] LC_TELEPHONE=C         LC_MEASUREMENT=C.UTF-8 LC_IDENTIFICATION=C
##
## time zone: UTC
## tzcode source: system (glibc)
##
## attached base packages:
## [1] stats     graphics  grDevices utils     datasets  methods   base
##
## other attached packages:
## [1] scales_1.4.0                   ggdist_3.3.3
## [3] ggplot2_4.0.3                  PublicationBiasBenchmark_0.3.0
##
## loaded via a namespace (and not attached):
##  [1] gtable_0.3.6         xfun_0.61            bslib_0.12.0
##  [4] htmlwidgets_1.6.4    lattice_0.22-9       vctrs_0.7.3
##  [7] tools_4.6.1          Rdpack_2.6.6         generics_0.1.4
## [10] curl_8.0.0           sandwich_3.1-3       tibble_3.3.1
## [13] pkgconfig_2.0.3      RColorBrewer_1.1-3   S7_0.2.2
## [16] desc_1.4.3           distributional_0.9.0 lifecycle_1.0.5
## [19] compiler_4.6.1       farver_2.1.2         stringr_1.6.0
## [22] textshaping_1.0.5    htmltools_0.5.9      sass_0.4.10
## [25] clubSandwich_0.7.0   yaml_2.3.12          pillar_1.11.1
## [28] pkgdown_2.2.1        jquerylib_0.1.4      cachem_1.1.0
## [31] tidyselect_1.2.1     digest_0.6.39        stringi_1.8.9
## [34] dplyr_1.2.1          purrr_1.2.2          labeling_0.4.3
## [37] fastmap_1.2.0        grid_4.6.1           cli_3.6.6
## [40] magrittr_2.0.5       triebeard_0.4.1      crul_1.6.0
## [43] osfr_0.2.9           withr_3.0.3          rmarkdown_2.32
## [46] httr_1.4.9           otel_0.2.0           ragg_1.5.2
## [49] zoo_1.9-1            kableExtra_1.4.1     memoise_2.0.1
## [52] evaluate_1.0.5       knitr_1.52           rbibutils_2.4.1
## [55] viridisLite_0.4.3    rlang_1.3.0          urltools_1.7.3.1
## [58] Rcpp_1.1.2           glue_1.8.1           httpcode_0.3.0
## [61] xml2_1.6.0           svglite_2.2.2        rstudioapi_0.19.0
## [64] jsonlite_2.0.0       R6_2.6.1             systemfonts_1.3.2
## [67] fs_2.1.0